Kaizen Teams

Dropdown

Table of Contents

Time to read

·

12

Published on

·

September 22, 2020

Last updated on

·

April 10, 2026

Francisco Martinez, Full-Stack Developer at Kaizen Softworks

Francisco Martinez

Samba lover

Full-Stack Developer

Technology

Technology

Improve Site Speed and Loading Times for Better SEO Rankings

Published on

·

April 10, 2026

Last updated on

·

April 10, 2026

Time to read

·

12

Francisco Martinez, Full-Stack Developer at Kaizen Softworks

Francisco Martinez

Full-Stack Developer

Across the internet today, we can find websites with many different types of features: sliders, videos, images, animations, and more that make them attractive to end users. However, all of these features can have a negative impact on one major factor: performance.

But wait, why should I care?

According to DoubleClick by Google, 53% of mobile site visits were abandoned if a page took longer than 3 seconds to load. Also, it was found that sites loading within 5 seconds had 35% lower bounce rates, 70% longer sessions, and 25% higher ad viewability than sites taking nearly four times longer at 19 seconds.

The performance impact can be measured in revenue too. DoubleClick found publishers whose sites loaded within five seconds earned up to twice as much ad revenue as sites loading within 19 seconds.

So you should care, and a lot. Performance can be the one thing that is making users ignore your website. It plays a major role when it comes to retaining users, user experience, and revenue. It also affects Google Rankings. That means performance is taken into account by Google when positioning your website in the search results higher (or lower) than your competitors.

So, how can we improve it?

Removing Render and Parsing Blocking Resources

A browser’s rendering engine is in charge of displaying what you see on the screen. In order to accomplish this, it has to parse HTML and create a DOM tree with all the existing HTML elements, render tree construction combining CSS attributes and the DOM tree, figure out each element’s position (layout process), and then paint the page.

When rendering a page, the rendering engine considers CSS as render blocking resources and scripts as render and parsing blocking resources.

That means that, by default, the page won’t be painted until the CSS and javascript are loaded, parsed, and executed. That presents a problem if your website has lots of CSS and javascript blocking parsing and rendering on your website, since performance can be affected dramatically and the site will take a long time to load.

Loading your website resources at the right time is essential to improving your website performance. If you load resources that avoid blocking parsing and rendering, your site will display much faster and the lesser critical content can be loaded in the background while the user interacts with the page. There are several ways to do this:

Using media print and onload=’this.media=’all’ to load non critical CSS (or loadCSS as an alternative)

Loading CSS with media type ‘print’ will tell the browser that the resource is not important because the media type doesn’t match the current environment (screen), and will load the stylesheet asynchronously without blocking page rendering.

<link rel="stylesheet” href="style.css" media=”print” onload=”this.media=’all’”>  

loadCSS is a popular library that also makes this possible.

<head>  
   <script id="loadcss">
     // load a CSS file just before the script element containing this code
     loadCSS( "path/to/mystylesheet.css", document.getElementById("loadcss") );
   </script>
</head>  

We also can combine this with ‘rel=preload’ (in supported browsers) if we want non critical CSS to be loaded as soon as possible.

<link rel="preload" href="style.css" as="style">  

This approach has a major downfall if applied to all CSS on the page: the browser will show a Flash of Unstyled Content (FOUC) before loading the CSS. This means that some essential CSS needs to block page rendering in order for the page to be displayed with its proper, critical styles. But asynchronously loading the remaining styles is a must for improving performance.

Efficiently loading JavaScript with defer and async

In order to load javascript efficiently without blocking HTML parsing, it’s very important that the scripts are placed in the right position. If placed in the header with no async or defer attributes, a lot of delay will occur because the browser will have to load and execute the script before continuing with HTML parsing and rendering. In order to avoid this, a common practice is to place the script tags before the  tag. However, async and defer are better approaches:

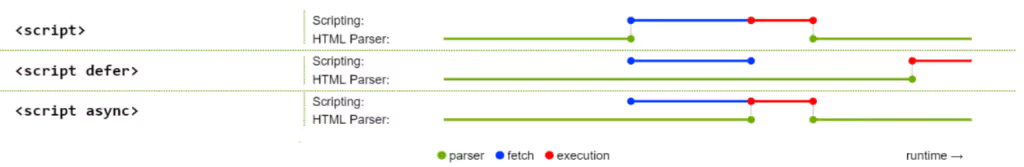
Async is a boolean attribute that you can place in a script tag that allows the browser to load the script in the background while it keeps parsing the HTML, and then execute the script as soon as it is loaded. This blocks the parsing if it happens before the browser finishes parsing. Async scripts are executed in random order as they become available.

Defer is also a boolean attribute that you can place in a script tag that allows the browser to load the script in the background while it keeps parsing the HTML. It then executes the script after the parsing is done. It’s similar to placing the script at the bottom of the page, the only difference being that it’s loaded in parallel while the HTML is parsing content. It also allows you to execute all deferred scripts in the order in which they appear on the document.

Note that both of these attributes are only useful if the scripts are declared in the header, otherwise they won’t do anything.

Comparing both attributes, async may block html parsing but defer guarantees not to. Neither of them guarantee anything on blocking rendering (however that can be done with the onLoad event).

Furthermore, their biggest difference is the execution order. Async scripts are executed in a random order as they become available, while deferred scripts are executed in the order of their appearance.

I recommend to use async loading in third party scripts where the loading order isn’t important (i.e. Google global site tag) and defer loading for scripts that need the whole DOM loaded and/or their relative execution order is important.

Comparing script loading performance, we obtain these results:

Image of a Scripting, featuring HTML code

These techniques (along with image lazy loading which is a critical performance improvement that we will comment on in a future post) were implemented on our site in order to improve its performance.

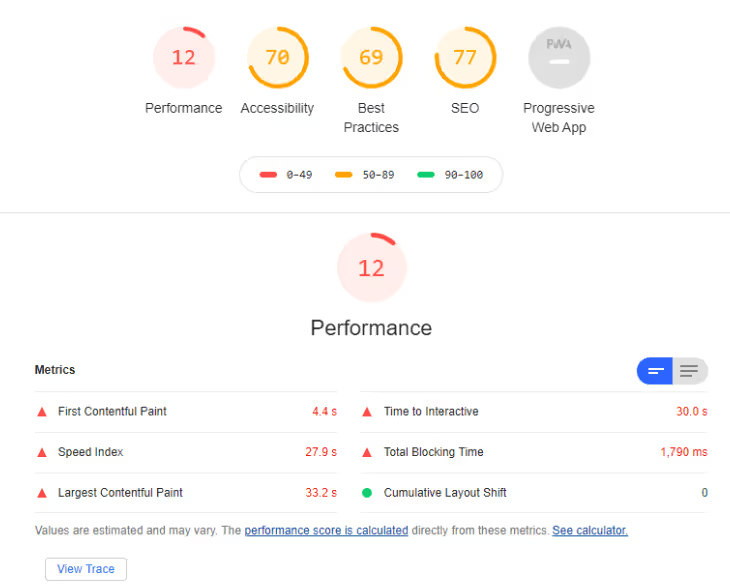
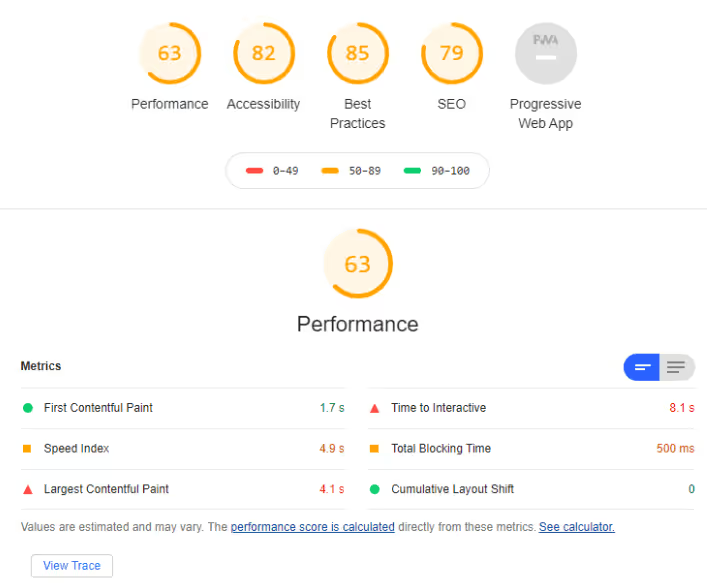
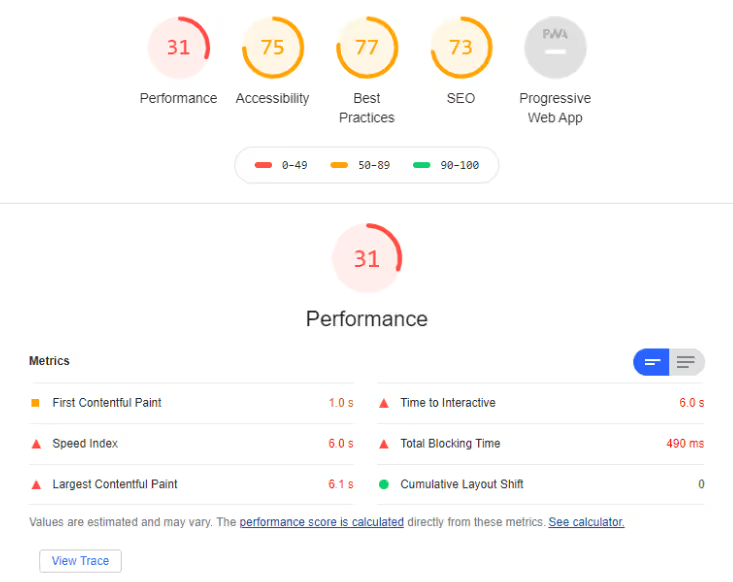
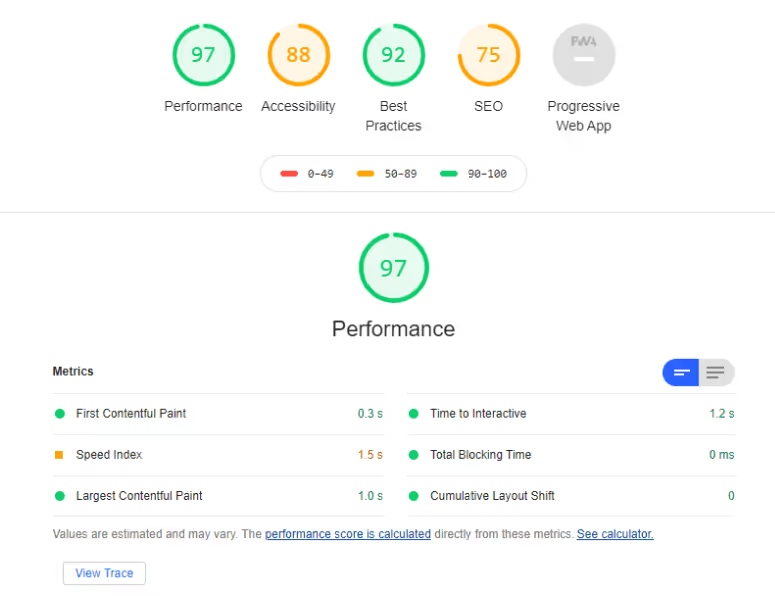
For comparison, the performance of the site’s old and new versions was measured locally using Lighthouse version 6. In the results shown below, we see a clear improvement in performance with the first contentful paint rendering almost four times faster in the newer version and the largest contentful paint rendering almost six times faster.

Mobile Version

Old Sit

SEO analysis dashboard, offering critical insights for effective search engine optimization strategies and performance tracking.'

New Site

SEO analysis dashboard, presenting essential information for enhancing website performance and search engine rankings.

Desktop Version

Old Site

SEO analysis dashboard, providing valuable data and metrics for optimizing online performance and search visibility

New Site

SEO analysis dashboard, displaying comprehensive data and insights for search engine optimization evaluation and strategy

Bibliography

Across the internet today, we can find websites with many different types of features: sliders, videos, images, animations, and more that make them attractive to end users. However, all of these features can have a negative impact on one major factor: performance.

But wait, why should I care?

According to DoubleClick by Google, 53% of mobile site visits were abandoned if a page took longer than 3 seconds to load. Also, it was found that sites loading within 5 seconds had 35% lower bounce rates, 70% longer sessions, and 25% higher ad viewability than sites taking nearly four times longer at 19 seconds.

The performance impact can be measured in revenue too. DoubleClick found publishers whose sites loaded within five seconds earned up to twice as much ad revenue as sites loading within 19 seconds.

So you should care, and a lot. Performance can be the one thing that is making users ignore your website. It plays a major role when it comes to retaining users, user experience, and revenue. It also affects Google Rankings. That means performance is taken into account by Google when positioning your website in the search results higher (or lower) than your competitors.

So, how can we improve it?

Removing Render and Parsing Blocking Resources

A browser’s rendering engine is in charge of displaying what you see on the screen. In order to accomplish this, it has to parse HTML and create a DOM tree with all the existing HTML elements, render tree construction combining CSS attributes and the DOM tree, figure out each element’s position (layout process), and then paint the page.

When rendering a page, the rendering engine considers CSS as render blocking resources and scripts as render and parsing blocking resources.

That means that, by default, the page won’t be painted until the CSS and javascript are loaded, parsed, and executed. That presents a problem if your website has lots of CSS and javascript blocking parsing and rendering on your website, since performance can be affected dramatically and the site will take a long time to load.

Loading your website resources at the right time is essential to improving your website performance. If you load resources that avoid blocking parsing and rendering, your site will display much faster and the lesser critical content can be loaded in the background while the user interacts with the page. There are several ways to do this:

Using media print and onload=’this.media=’all’ to load non critical CSS (or loadCSS as an alternative)

Loading CSS with media type ‘print’ will tell the browser that the resource is not important because the media type doesn’t match the current environment (screen), and will load the stylesheet asynchronously without blocking page rendering.

<link rel="stylesheet” href="style.css" media=”print” onload=”this.media=’all’”>  

loadCSS is a popular library that also makes this possible.

<head>  
   <script id="loadcss">
     // load a CSS file just before the script element containing this code
     loadCSS( "path/to/mystylesheet.css", document.getElementById("loadcss") );
   </script>
</head>  

We also can combine this with ‘rel=preload’ (in supported browsers) if we want non critical CSS to be loaded as soon as possible.

<link rel="preload" href="style.css" as="style">  

This approach has a major downfall if applied to all CSS on the page: the browser will show a Flash of Unstyled Content (FOUC) before loading the CSS. This means that some essential CSS needs to block page rendering in order for the page to be displayed with its proper, critical styles. But asynchronously loading the remaining styles is a must for improving performance.

Efficiently loading JavaScript with defer and async

In order to load javascript efficiently without blocking HTML parsing, it’s very important that the scripts are placed in the right position. If placed in the header with no async or defer attributes, a lot of delay will occur because the browser will have to load and execute the script before continuing with HTML parsing and rendering. In order to avoid this, a common practice is to place the script tags before the  tag. However, async and defer are better approaches:

Async is a boolean attribute that you can place in a script tag that allows the browser to load the script in the background while it keeps parsing the HTML, and then execute the script as soon as it is loaded. This blocks the parsing if it happens before the browser finishes parsing. Async scripts are executed in random order as they become available.

Defer is also a boolean attribute that you can place in a script tag that allows the browser to load the script in the background while it keeps parsing the HTML. It then executes the script after the parsing is done. It’s similar to placing the script at the bottom of the page, the only difference being that it’s loaded in parallel while the HTML is parsing content. It also allows you to execute all deferred scripts in the order in which they appear on the document.

Note that both of these attributes are only useful if the scripts are declared in the header, otherwise they won’t do anything.

Comparing both attributes, async may block html parsing but defer guarantees not to. Neither of them guarantee anything on blocking rendering (however that can be done with the onLoad event).

Furthermore, their biggest difference is the execution order. Async scripts are executed in a random order as they become available, while deferred scripts are executed in the order of their appearance.

I recommend to use async loading in third party scripts where the loading order isn’t important (i.e. Google global site tag) and defer loading for scripts that need the whole DOM loaded and/or their relative execution order is important.

Comparing script loading performance, we obtain these results:

Image of a Scripting, featuring HTML code

These techniques (along with image lazy loading which is a critical performance improvement that we will comment on in a future post) were implemented on our site in order to improve its performance.

For comparison, the performance of the site’s old and new versions was measured locally using Lighthouse version 6. In the results shown below, we see a clear improvement in performance with the first contentful paint rendering almost four times faster in the newer version and the largest contentful paint rendering almost six times faster.

Mobile Version

Old Sit

SEO analysis dashboard, offering critical insights for effective search engine optimization strategies and performance tracking.'

New Site

SEO analysis dashboard, presenting essential information for enhancing website performance and search engine rankings.

Desktop Version

Old Site

SEO analysis dashboard, providing valuable data and metrics for optimizing online performance and search visibility

New Site

SEO analysis dashboard, displaying comprehensive data and insights for search engine optimization evaluation and strategy

Bibliography

Related Articles

View all articles

·

Sep 23, 2026

The cost of turnover in software teams (and how to protect context)

Developer turnover costs capacity for weeks and context for months. What software teams lose, how to measure it, and four questions to ask any partner.

12 read time

Read more

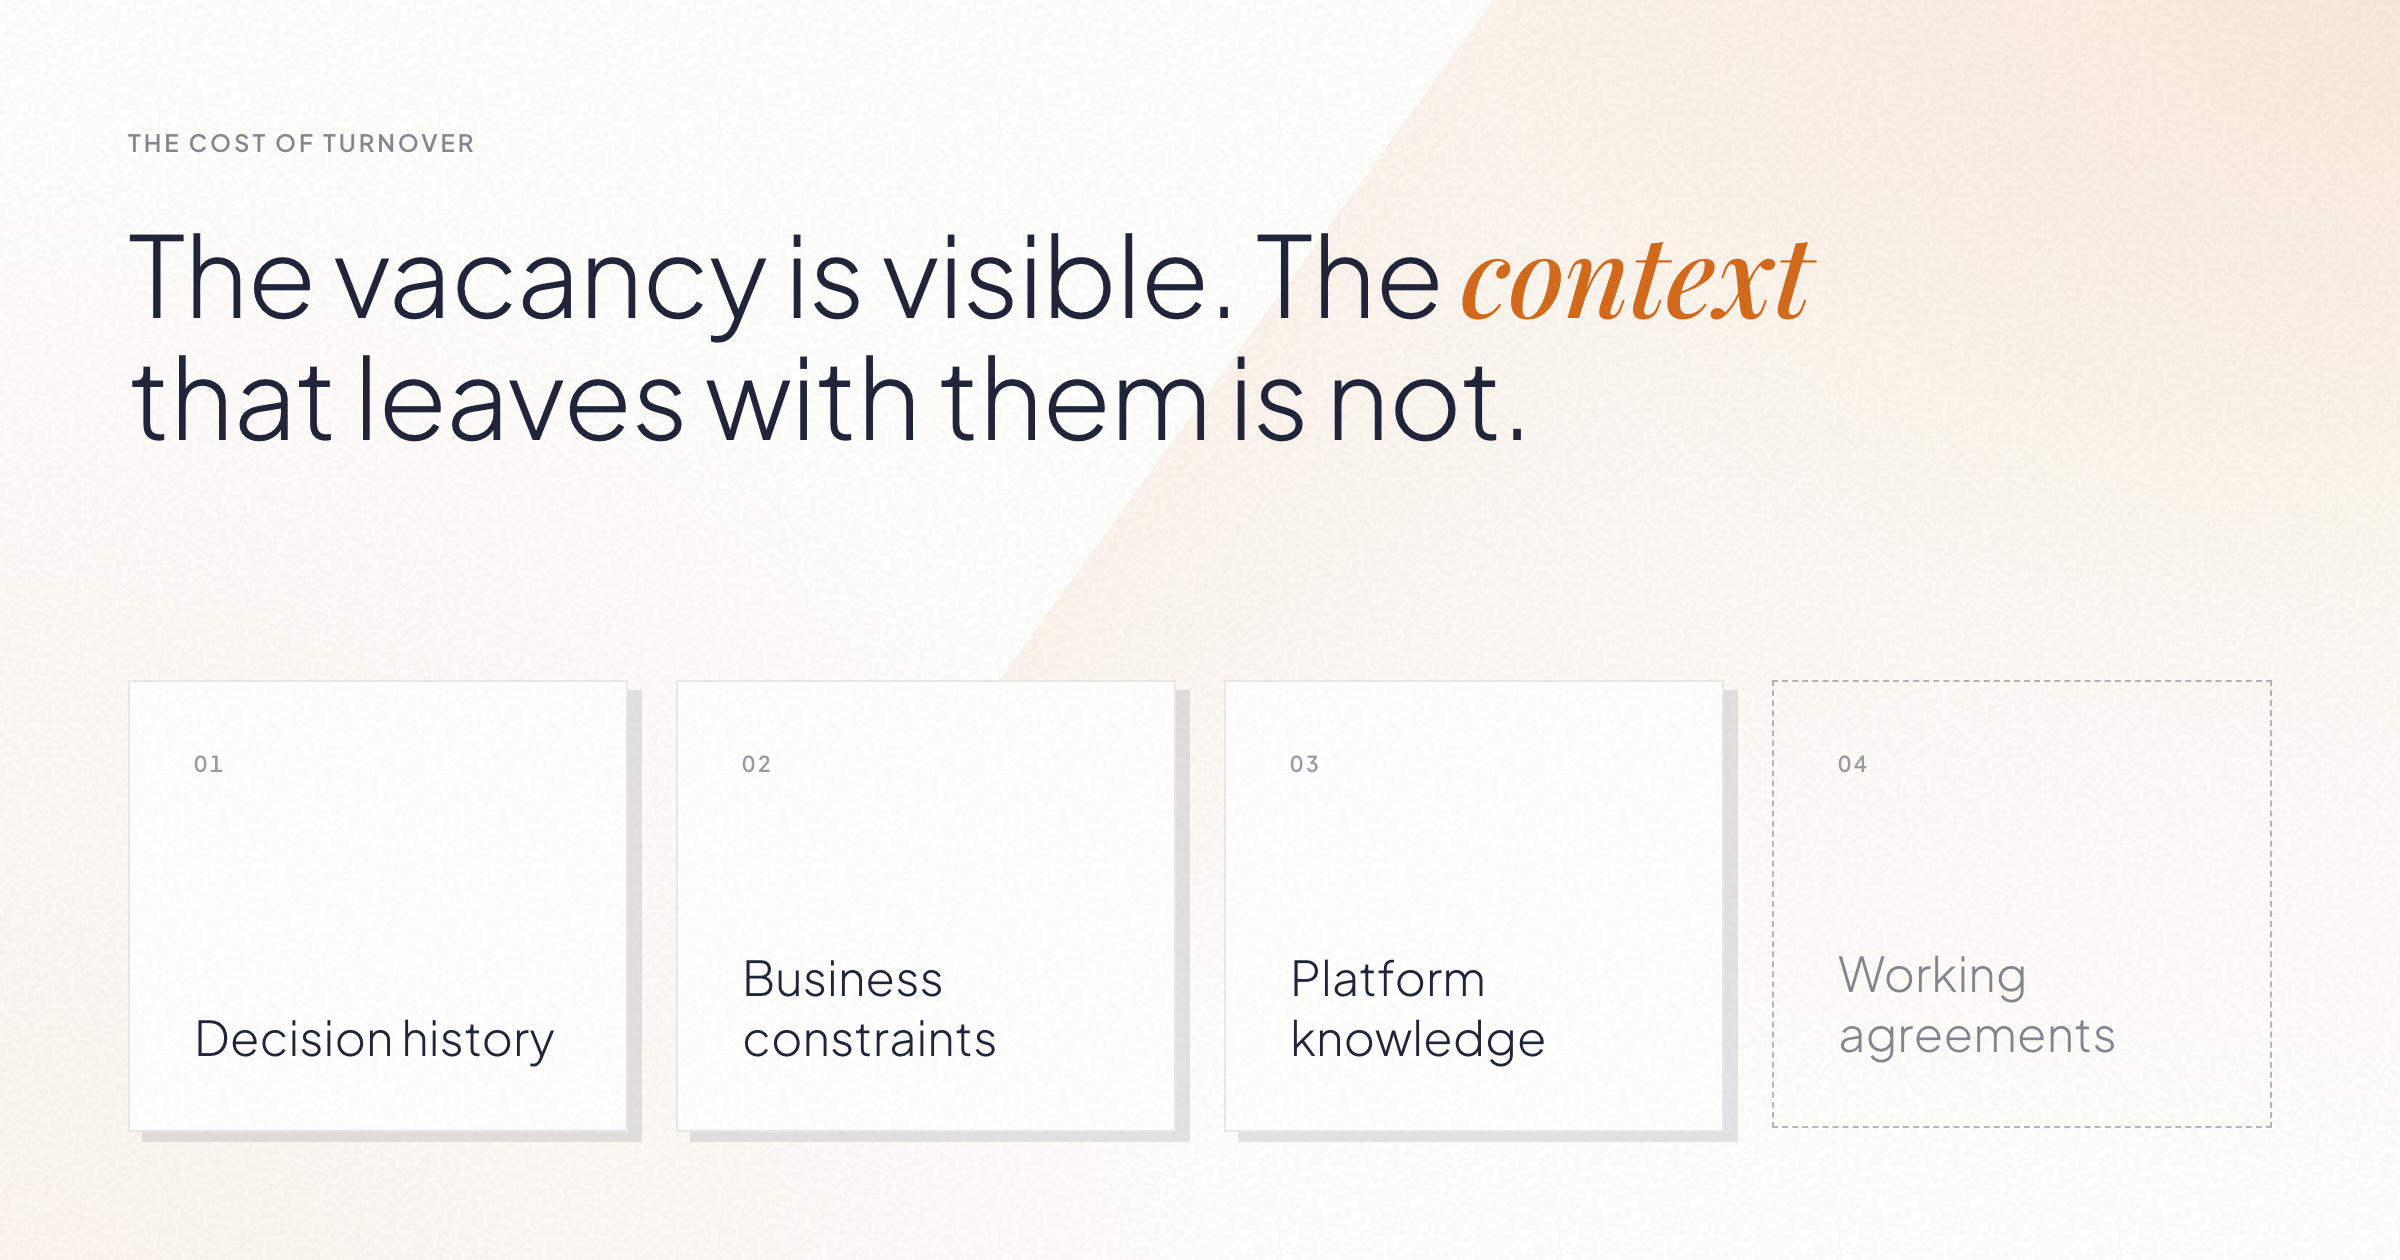
When an engineer leaves a software team, the visible cost is a vacancy. The expensive cost is invisible: the context that leaves with them, and the months the rest of the team spends rebuilding it.

We've seen this play out across client projects for years. This post covers what walks out the door when someone leaves, how to think about the real cost, and a simple framework for making better decisions when it happens, whether you work with us or not.

The short version

  • Turnover costs capacity for weeks. It costs context for months.
  • Context is specific and nameable: decision history, business constraints, platform knowledge, and working agreements.
  • The reflex to replace the exact profile that left is often the most expensive option. Sometimes the answer is already on your team.
  • You can evaluate any software partner on continuity with four questions. We include our own answers below.

What does a software team lose when someone leaves?

A software team loses two things when someone leaves: capacity and context. Capacity is visible and replaceable. Context is neither.

Context sounds abstract, so let's make it concrete. It comes in four forms:

Type of context What it looks like
Decision history Why the architecture is the way it is. Which alternatives were already tried and discarded, and why.
Business constraints The regulations, integrations, and non-negotiables that make certain changes risky.
Platform knowledge Where the fragile parts are. Which dependency breaks what. The bugs the team learned to avoid.
Working agreements How decisions get made with the client. What "done" means on this project. Who to ask about what.

A new hire can match the departed engineer's skills on day one. The four things above take months to rebuild, and while they're being rebuilt, the whole team pays: meetings run longer, settled decisions get relitigated, and senior people spend their time explaining instead of building.

What is the cost of developer turnover?

The cost of developer turnover is the ramp-up period multiplied across the team, not the recruiting fee. The math works like this:

The replacement operates below full productivity for months while they absorb the four types of context above. During that same period, the existing team diverts hours to onboarding, re-explaining, and reviewing more carefully than usual. So the cost is one person's ramp-up plus a productivity tax on everyone around them, at exactly the moment the project needed continuity.

This is why turnover gets underestimated. On the day someone resigns, it looks like an operational issue: fill the seat, keep moving. The bill arrives over the following two quarters, itemized as slower delivery, longer meetings, and decisions that used to be obvious.

Why replacing the exact profile is often the wrong reflex

The first thought is to backfill with an identical hire. Sometimes that's right. But the skill that is left with that person may be easier to replace than the context they gained: the client relationship, the platform history, and the judgment behind past decisions.

Someone already on the team may be able to learn a specific skill faster than a new specialist can learn the client, the platform, and the history behind the work. For a real example and four questions to ask before starting a search, see “Why adding people doesn't always fix a struggling team.”

How to evaluate a software partner on continuity

If you work with an external team, their turnover becomes your turnover. Four questions tell you most of what you need to know, and any serious partner should answer them with numbers:

What's your team retention rate? Ours has averaged 96% in recent years. Whatever the number, ask how it's measured and over what period.

How do you know people want to stay? Retention tells you what happened. An engagement measure tells you what's coming. Our eNPS (employee Net Promoter Score) is +83.

How do you spread context across the team? One person holding all the context is a risk with a name: bus factor. Ask how knowledge gets documented and shared, so continuity doesn't depend on any single individual.

Do you prepare capacity before it's needed? On some projects, we bring people up to speed on the business and the platform before there's an immediate need. When the project needs more capacity, nobody starts from zero.

These questions work on any vendor, including us. That's the point.
·

Sep 21, 2026

When PMs can ship code, what changes for Engineering?

AI coding agents give Product and Engineering more autonomy, plus a new coordination problem. See how a two-cycle model keeps both moving.

12 read time

Read more

AI has changed what Product Managers can do.

A PM can now go from an idea to working software in hours. They can build a flow, put it in front of a customer, learn from it, change it, and test again without waiting for every iteration to go through Engineering.

That creates an opportunity for product teams. It also creates a new challenge.

Just because a PM can build something doesn’t mean that thing is ready to become production software.

If we don’t rethink how Product and Engineering work together, faster prototyping can become more code for Engineering to untangle, more unclear ownership, and more pressure to turn experiments into production features.

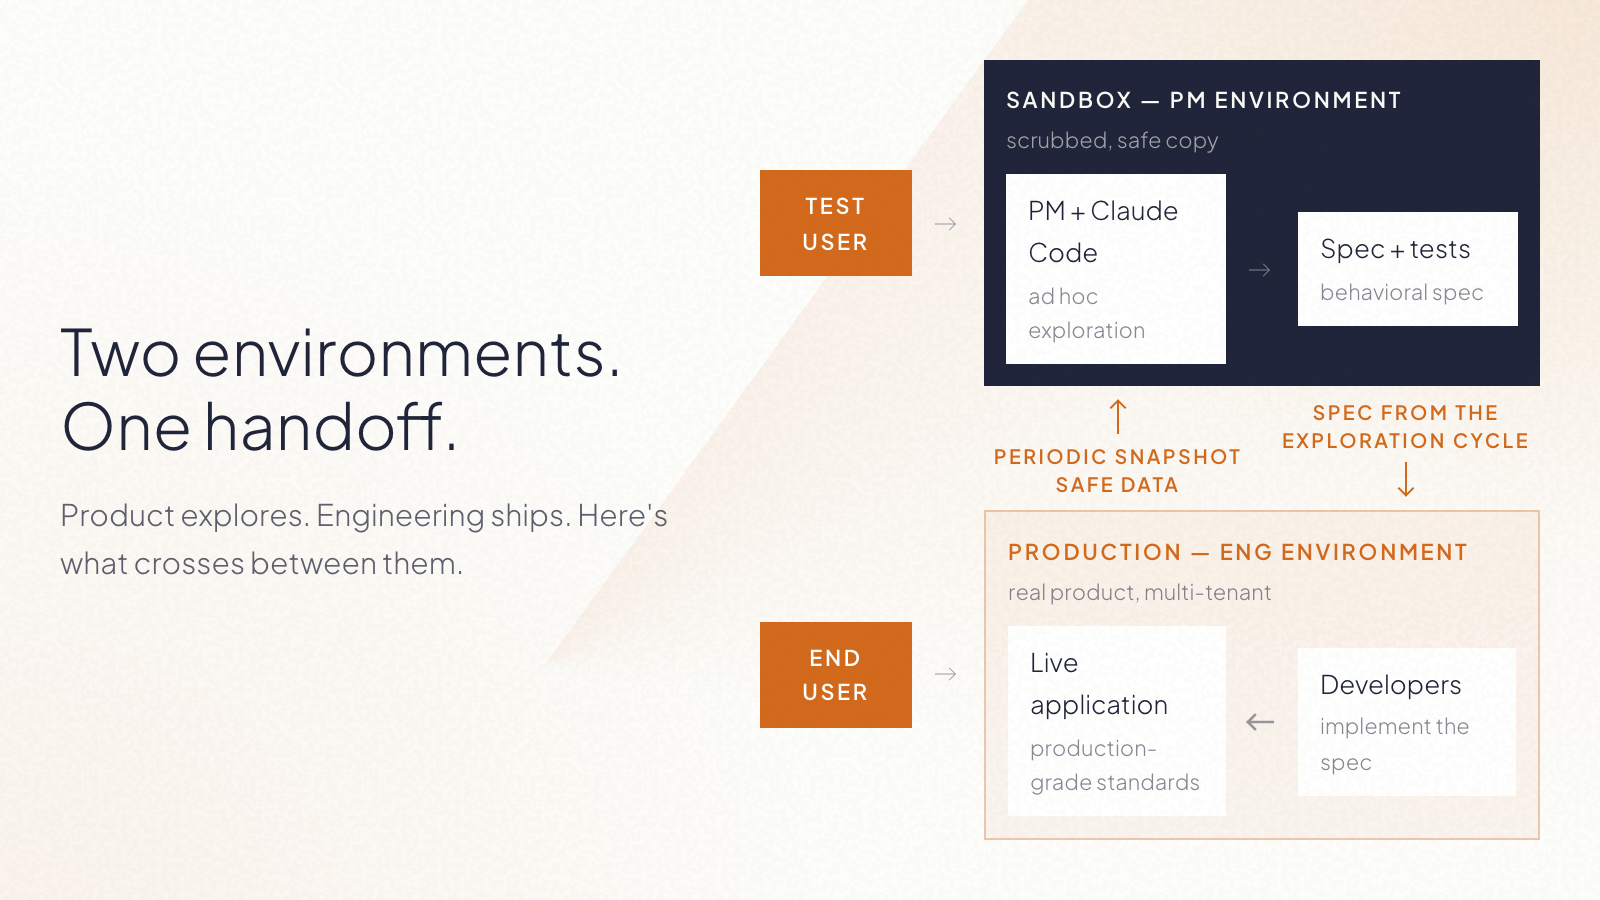
The answer is to separate exploration from construction.

PMs and engineers are solving different problems

During product discovery, the PM is trying to answer: Should we build this?

That means testing assumptions, changing direction quickly, throwing things away, and getting something real enough in front of a customer to learn from it.

Engineering is solving a different problem: How do we build this correctly?

That means thinking about architecture, security, maintainability, performance, edge cases, and everything else required for software that has to live in production.

Both need AI. But they don’t need the same working conditions.

Exploration benefits from speed, autonomy, and low friction. Construction needs stronger guarantees and guardrails. Trying to optimize the same environment for both creates tension.

So instead of asking how PMs can safely contribute code to the production codebase, there’s a more useful question: What if PMs had their own space to build and validate ideas?

Give PMs a safe place to explore

A PM working with an AI coding agent can build functional versions of new ideas. Not a Figma screen. Not a ticket describing what something might do.

Working software that can be used to test the product experience. The important part is that this environment is separate from production.

That boundary gives the PM freedom to experiment without requiring the same controls we’d expect from production software. The environment can be designed so experiments can’t affect the live product or access things they shouldn’t.

Now the PM’s workflow can look more like:

Idea → build → test with users → learn → iterate

Engineering doesn’t need to be pulled into every cycle.  Engineering still matters. It  gets brought in once Product has stronger evidence about what’s worth building.

The prototype shouldn’t be the handoff

This is where things can go wrong.

If a PM spends two days building something with AI and then gives the repository to Engineering saying, “It mostly works, can you finish it?”, we haven’t improved the product development process. We may have just moved the mess downstream.

The prototype should help answer product questions. It shouldn’t make technical decisions on Engineering’s behalf.

What Engineering needs from exploration is intent.

  • What does the feature need to do?
  • How should it behave?
  • What did we learn from customers?
  • What happens in the important edge cases?
  • How will we know when the production version works as intended?

That becomes the handoff.

At Kaizen, we’ve been exploring a model where the bridge between the two cycles is a behavioral specification and a test plan, supported by the working prototype as a reference. The implementation itself stays behind.

What crosses into construction is the spec: a behavioral description, a test plan, and a link to the prototype as reference. The prototype itself stays where it was built.

In simple terms:

Product owns the what. Engineering owns the how.

That distinction matters even more now that AI makes it so easy for both sides to generate code.

What the workflow could look like

A PM starts with a product hypothesis. Instead of immediately turning it into a backlog item, they use AI to build enough of the experience to test it. They put it in front of users. They discover that part of the original idea was wrong. So they change it. They test again.

Once the problem and desired behavior are clear enough, the PM closes the exploration cycle with a clear specification and acceptance criteria.

Engineering then starts from that understanding, not from the PM’s experimental code only. They decide how the feature fits into the architecture, how it should be implemented, what needs to be verified, and how it reaches production.

The result is two parallel forms of autonomy:

  • PMs don’t need Engineering for every experiment.
  • Engineers don’t inherit implementation decisions from every experiment.

More autonomy doesn’t have to mean less ownership.

AI can make discovery faster

A lot of the conversation around AI in software teams is still about developer productivity. How much faster can we write code? How much implementation can an agent take on?

Those questions matter. But for Product, there may be an even bigger opportunity upstream. AI can shorten the distance between having an idea and learning whether that idea is any good.

That changes what PMs can bring to an engineering team. Instead of: “We think customers want this.” They can increasingly say: “We tested this behavior with customers. Here’s what worked, what didn’t, and exactly what we now need the product to do.”

That’s a much better starting point for building production software.

If you have a prototype and want to take the idea into production, we can help you determine what needs to happen next.

llms.txt