Kaizen Teams

Dropdown

Table of Contents

Time to read

·

12

Published on

·

August 14, 2026

Last updated on

·

August 27, 2026

Santiago Chiappa, Backend Developer at Kaizen Softworks

Santiago Chiappa

Motorcycle enthusiast

Backend Developer

AI

AI

UX Design

UX Design

What are the risks of Generative UI in production?

Published on

·

August 27, 2026

Last updated on

·

August 27, 2026

Time to read

·

12

Santiago Chiappa, Backend Developer at Kaizen Softworks

Santiago Chiappa

Backend Developer

Generative UI assembles the interface around what each user is trying to do, instead of showing everyone the same fixed screen. That flexibility comes with real considerations: keeping the experience consistent, secure, and easy to support once it's live. This post covers what generative UI is worth building for, what it costs, and how teams keep it under control.

Generative UI works best when the experience is dynamic, but the system behind it stays tightly controlled.

Start by defining which parts of the interface can change, which cannot, and what must be validated before anything reaches the user.

TL;DR

  • Interfaces can adapt to user context, support more variations without designing every screen by hand, and reduce unnecessary steps in a workflow.
  • The trade-offs include inconsistent experiences, unreliable or unsafe output, added latency and infrastructure cost, and harder analytics and debugging.
  • Better prompting can reduce unwanted behavior, but it cannot guarantee reliability, security, or consistency. Those controls need to exist around the model: a stable interface shell, a closed component catalog, validation of model output, session-level logging, and model routing with fallback options.
  • Every control introduces a trade-off. No architecture maximizes flexibility, reliability, privacy, performance, and cost at the same time.

What does generative UI make possible?

Interfaces that adapt to context

The interface can adapt to what a person is trying to do instead of relying only on a persona defined at design time. Steps can reorder or disappear based on intent. It can change how much information it shows and what it emphasizes. Copy can adapt to the user's locale and context instead of relying on literal translation.

More interface variations with less custom development

A small set of components can support many variations without designing each screen separately. The system can also support workflows the team did not design as individual screens, as long as the required components and actions already exist.

Fewer steps between intent and action

The interface can hide controls a task does not need, reducing the number of steps required to complete it. Generative UI can also help teams test different ways of presenting the same task. Whether that improves completion or conversion depends on the workflow.

What can go wrong with generative UI?

Experience consistency risks

When layouts change between users or sessions, they can break muscle memory and make support harder. They can also drift from the design system or disrupt accessibility patterns that depend on consistent structure.

Reliability and security risks

The system should not trust model output by default. A model can render a button that does nothing, display fabricated data in a component, or produce a state the team never tested. Prompt injection can push it toward components, content, or actions the system should not allow. Weak controls can expose sensitive data or allow actions and interface states the product should block.

Performance and infrastructure risks

A generative interface also inherits the model layer's latency, cost, and availability risks. Waiting on an LLM to generate a layout adds delay before a page renders. Each generation uses processing resources, and hosted models usually add usage-based cost. Relying on one provider also exposes your product to outages, API changes, price increases, and deprecations.

Analytics and debugging risks

Standard analytics often assume a fixed set of screens. Heatmaps and funnels become harder to compare when users see different layouts. Reproducing a bug also gets harder when you cannot reopen the exact screen the user saw.

How do you control these risks?

Prompts can reduce unwanted behavior, but they cannot enforce which components the system may render or which actions it may allow. Those limits need to be enforced in the architecture around the model.

What parts of a generative interface should remain fixed?

Keep global navigation, account and security controls, primary actions, critical transaction controls, and accessibility-critical structure fixed. Let the model modify only the content and controls that benefit from adaptation.

Fixed navigation preserves familiar interaction patterns. A stable structure also makes accessibility testing, branding, and support more predictable.

How do you stop generative UI from creating broken interfaces?

Do not let the model generate arbitrary UI code. Have it return structured configuration instead. The schema should specify the component, its data, and its position. Validate that output against a closed catalog before rendering it.

The model should not write HTML, CSS, or JavaScript or choose anything outside that catalog. This reduces invalid layouts and unsupported combinations. This is the declarative approach we covered in Part 1.

How should teams test and secure generative UI?

Treat model output as untrusted input. Validate it against the schema and component allowlist, sanitize content, and keep authorization outside the model.

Add content security policies and prompt-injection defenses based on what the model can access and what actions it can trigger. Pay particular attention to user-provided content, privileged actions, sensitive data, and external tools.

Limit valid component combinations, then use visual regression and property-based tests to exercise unexpected inputs and edge cases.

Minimize sensitive data sent to the model. Mask or anonymize it before generation when the task does not require the original values.

How do you monitor a UI that looks different for every user?

Record enough context to reconstruct each generated interface. That includes detected intent, model version, generated configuration, rendered components, task completion, and errors, all tied to the session.

That record lets teams segment analytics by generated experience and reconstruct what a user saw during a specific session.

How do you control latency, cost, and outages?

Cache reusable results where freshness and privacy allow. Show a skeleton layout immediately and stream the rest in. Route simpler requests to smaller or local models, and reserve larger ones for complex requests. Put providers behind the same integration layer so you can switch models or fall back to a static experience during an outage.

What it controls Risks it mitigates
Stable interface shell Keeps navigation, account controls, and primary actions fixed Muscle memory loss, brand drift, accessibility gaps, support friction
Component-based UI Model outputs configuration, not code UI hallucinations, broken layouts, brand inconsistency, testing complexity
Untrusted-input handling Schema validation, allowlists, sanitization, sensitive-data controls Prompt injection, unsafe states, fabricated actions, privacy exposure
Session-level logging Records intent, generated configuration, rendered components, and outcome Fragmented analytics, hard-to-reproduce bugs, support friction
Model routing and fallback Caching, streaming, model routing, provider switching Latency, model cost, provider downtime, difficulty switching providers

What do these controls cost you?

Keeping more of the interface fixed protects consistency but limits personalization. Limiting combinations makes the system easier to test but reduces how much it can vary. Caching lowers cost, but cached output can go stale.

Running models locally can reduce how much sensitive data leaves your infrastructure, but it adds systems your team has to operate and maintain. Detailed session logs can make support easier, but they also create storage, retention, and privacy requirements.

No architecture maximizes flexibility, reliability, privacy, performance, and cost at once. You need to decide which trade-offs matter most for each workflow and design around them.

Generative UI assembles the interface around what each user is trying to do, instead of showing everyone the same fixed screen. That flexibility comes with real considerations: keeping the experience consistent, secure, and easy to support once it's live. This post covers what generative UI is worth building for, what it costs, and how teams keep it under control.

Generative UI works best when the experience is dynamic, but the system behind it stays tightly controlled.

Start by defining which parts of the interface can change, which cannot, and what must be validated before anything reaches the user.

TL;DR

  • Interfaces can adapt to user context, support more variations without designing every screen by hand, and reduce unnecessary steps in a workflow.
  • The trade-offs include inconsistent experiences, unreliable or unsafe output, added latency and infrastructure cost, and harder analytics and debugging.
  • Better prompting can reduce unwanted behavior, but it cannot guarantee reliability, security, or consistency. Those controls need to exist around the model: a stable interface shell, a closed component catalog, validation of model output, session-level logging, and model routing with fallback options.
  • Every control introduces a trade-off. No architecture maximizes flexibility, reliability, privacy, performance, and cost at the same time.

What does generative UI make possible?

Interfaces that adapt to context

The interface can adapt to what a person is trying to do instead of relying only on a persona defined at design time. Steps can reorder or disappear based on intent. It can change how much information it shows and what it emphasizes. Copy can adapt to the user's locale and context instead of relying on literal translation.

More interface variations with less custom development

A small set of components can support many variations without designing each screen separately. The system can also support workflows the team did not design as individual screens, as long as the required components and actions already exist.

Fewer steps between intent and action

The interface can hide controls a task does not need, reducing the number of steps required to complete it. Generative UI can also help teams test different ways of presenting the same task. Whether that improves completion or conversion depends on the workflow.

What can go wrong with generative UI?

Experience consistency risks

When layouts change between users or sessions, they can break muscle memory and make support harder. They can also drift from the design system or disrupt accessibility patterns that depend on consistent structure.

Reliability and security risks

The system should not trust model output by default. A model can render a button that does nothing, display fabricated data in a component, or produce a state the team never tested. Prompt injection can push it toward components, content, or actions the system should not allow. Weak controls can expose sensitive data or allow actions and interface states the product should block.

Performance and infrastructure risks

A generative interface also inherits the model layer's latency, cost, and availability risks. Waiting on an LLM to generate a layout adds delay before a page renders. Each generation uses processing resources, and hosted models usually add usage-based cost. Relying on one provider also exposes your product to outages, API changes, price increases, and deprecations.

Analytics and debugging risks

Standard analytics often assume a fixed set of screens. Heatmaps and funnels become harder to compare when users see different layouts. Reproducing a bug also gets harder when you cannot reopen the exact screen the user saw.

How do you control these risks?

Prompts can reduce unwanted behavior, but they cannot enforce which components the system may render or which actions it may allow. Those limits need to be enforced in the architecture around the model.

What parts of a generative interface should remain fixed?

Keep global navigation, account and security controls, primary actions, critical transaction controls, and accessibility-critical structure fixed. Let the model modify only the content and controls that benefit from adaptation.

Fixed navigation preserves familiar interaction patterns. A stable structure also makes accessibility testing, branding, and support more predictable.

How do you stop generative UI from creating broken interfaces?

Do not let the model generate arbitrary UI code. Have it return structured configuration instead. The schema should specify the component, its data, and its position. Validate that output against a closed catalog before rendering it.

The model should not write HTML, CSS, or JavaScript or choose anything outside that catalog. This reduces invalid layouts and unsupported combinations. This is the declarative approach we covered in Part 1.

How should teams test and secure generative UI?

Treat model output as untrusted input. Validate it against the schema and component allowlist, sanitize content, and keep authorization outside the model.

Add content security policies and prompt-injection defenses based on what the model can access and what actions it can trigger. Pay particular attention to user-provided content, privileged actions, sensitive data, and external tools.

Limit valid component combinations, then use visual regression and property-based tests to exercise unexpected inputs and edge cases.

Minimize sensitive data sent to the model. Mask or anonymize it before generation when the task does not require the original values.

How do you monitor a UI that looks different for every user?

Record enough context to reconstruct each generated interface. That includes detected intent, model version, generated configuration, rendered components, task completion, and errors, all tied to the session.

That record lets teams segment analytics by generated experience and reconstruct what a user saw during a specific session.

How do you control latency, cost, and outages?

Cache reusable results where freshness and privacy allow. Show a skeleton layout immediately and stream the rest in. Route simpler requests to smaller or local models, and reserve larger ones for complex requests. Put providers behind the same integration layer so you can switch models or fall back to a static experience during an outage.

What it controls Risks it mitigates
Stable interface shell Keeps navigation, account controls, and primary actions fixed Muscle memory loss, brand drift, accessibility gaps, support friction
Component-based UI Model outputs configuration, not code UI hallucinations, broken layouts, brand inconsistency, testing complexity
Untrusted-input handling Schema validation, allowlists, sanitization, sensitive-data controls Prompt injection, unsafe states, fabricated actions, privacy exposure
Session-level logging Records intent, generated configuration, rendered components, and outcome Fragmented analytics, hard-to-reproduce bugs, support friction
Model routing and fallback Caching, streaming, model routing, provider switching Latency, model cost, provider downtime, difficulty switching providers

What do these controls cost you?

Keeping more of the interface fixed protects consistency but limits personalization. Limiting combinations makes the system easier to test but reduces how much it can vary. Caching lowers cost, but cached output can go stale.

Running models locally can reduce how much sensitive data leaves your infrastructure, but it adds systems your team has to operate and maintain. Detailed session logs can make support easier, but they also create storage, retention, and privacy requirements.

No architecture maximizes flexibility, reliability, privacy, performance, and cost at once. You need to decide which trade-offs matter most for each workflow and design around them.

Common questions

Do you need all five controls before shipping?

Start with component-based UI and a stable interface shell. Those two controls reduce layout drift, unsupported components, and inconsistent navigation. Add more detailed session logging and fallback behavior as the number of generated states and production dependencies grows.

Can these be added to a feature that's already live?

Most can. Schema validation, an allowlisted catalog, and session logging can usually be added without rebuilding the whole feature. Changing the interface shell may require more work because it changes which parts of the experience stay fixed.

Does this mean redesigning your design system?

No. The model should stay within the components, styles, and design tokens your design system already defines. If the design system has gaps, you will need to fix them whether or not you use generative UI.

Which pattern should teams build first?

Start with component-based UI. A closed catalog and validated schema give you something concrete to constrain, test, and log.

1
What is the difference between working with Kaizen versus a single designer?

Related Articles

View all articles

·

Aug 28, 2026

About Catalyst 26: Partnerships & Ecosystem Conference

Everything to know about Catalyst 26: dates, price, who attends, both keynote recaps, and when the next Catalyst event is.

12 read time

Read more

Catalyst 26 was Partnership Leaders' fifth annual conference for partnership, ecosystem, and go-to-market professionals. It took place August 25 and 26, 2026, at the Marriott Hotel at the Brooklyn Bridge in New York, with more than 1,000 attendees and 70-plus speakers from companies including Anthropic, OpenAI, Google, Microsoft, IBM, BCG, and Siemens.

Dates August 25–26, 2026
Location Marriott Hotel at the Brooklyn Bridge, Brooklyn, NY
Edition 5th annual
Attendees 1,000+ partnership, ecosystem, and GTM professionals
Speakers 70+, including people from Anthropic, OpenAI, Google, Microsoft, IBM, BCG, and Siemens.
Price $849 early bird, rising to $999, then $1,999

Who Catalyst events are for

Catalyst brought together people building and running partner programs across SaaS, AI, consulting, systems integration, agencies, and major cloud platforms.

Attendees included executives leading partnership organizations, and people working directly in alliances, partner sales, marketing, operations, strategy, and enablement.

What Catalyst 26 is like

You can look at the agenda before a conference and have a pretty good idea of what you'll find. Being there is different.

This year's theme was "Navigating Frontier Ecosystems". Anthropic's Head of Partnerships and one of OpenAI's partner program leads appeared on the same agenda as people from Oracle, Siemens, IBM, and BCG, companies that have run formal partner programs for two decades.

That mix was one of the most interesting parts of the conference. Newer AI companies were discussing partner tiers, co-selling, and joint delivery alongside companies where those models have been part of their business for years.

What Catalyst 26 covered

Catalyst 26 split its sessions into eight pillars:

  • Advancing Organizational Maturity: turning partnerships into something measured and repeatable instead of one founder doing favors for another.
  • Become a Strategic Partner: getting partnerships involved when product and business decisions are made, not told about them afterward.
  • Frontier Partner Experience: adapting partner programs as AI changes how companies build and integrate products.
  • Path to CPO: career sessions for people aiming to lead partnerships at the executive level.
  • Co-Build: two companies building something together.
  • Co-Market: two companies running a campaign together.
  • Co-Sell: two sales teams working the same deal.
  • Co-Serve: two companies delivering the same engagement to a client.

Catalyst 26 sessions

Day 1 Keynote

The Day 1 keynote brought together Partnership Leaders’ CEO Asher Mathew, Tribe AI’s Co-founder & CEO Jaclyn Rice Nelson, Anthropic’s Head of Partnerships Phil Samenuk, and Boomi’s Chairman & CEO Steve Lucas.

Their discussion focused on how companies are relying on partners to build, sell, and deliver products across AI, cloud, and enterprise software. A few points stood out:

  • More companies have dedicated partner teams now, which means a generic, one-size-fits-all partner program doesn't cut it anymore. Partners show up when the program fits how they work.
  • New AI products and cloud services are shipping so fast that a partner program can't just get set once and left alone. Incentives, support, and how you work together need regular updates.
  • Partnerships also came up as a way to access data a company couldn’t reach on its own, whether that meant getting access to it, combining it, or putting it to use.
  • AI doesn't change the basics of a good partnership. Account planning, clear ownership, and relationships built over time still matter most.

Day 2 Keynote

The Day 2 keynote featured Ramp’s Lead Economist Ara Kharazian, Eliza’s Founder Brian Benedict, Siemens’ EVP Global Partner Ecosystem Dion Smith, and Oracle’s SVP, Partner Sales & Operations Strategy Leah Yomtovian.

A few points stood out:

  • The spending data told a slower story than expected: AI adoption is mostly going toward productivity gains and task automation, not some overnight shift.
  • Siemens is in the middle of folding more than 68,000 partners and roughly 200 separate programs into a single global one, mainly to make it easier to coordinate across IT and operational technology.
  • Oracle's approach is a running "listening tour": every partner gets the same baseline benefits, then incentives and credits get layered based on the type of partner and how they work with Oracle.
  • There was also talk of a newer kind of service team: bring in engineers, turn AI requirements into working products, and reuse delivery methods that already work instead of starting from scratch each time.

Next Catalyst events

The date and location of Catalyst 27 hasn’t been announced yet. In the meantime, you can check out the half-day Catalyst Summits in different cities:

  • October 20, 2026 - Seattle
  • October 27, 2026 - Chicago
  • October 2026 - Los Angeles
  • December 2026 - Singapore

Check Partnership Leaders’ events page for updates.
·

Aug 26, 2026

Why adding people doesn't always fix a struggling team

Learn when a software team should hire, wait, reorganize, or build skills internally, and how to tell which option will actually help.

12 read time

Read more

When a client asks to hire someone new, a common reaction is to open a search. There's more work, more pressure, and new features to build. It seems like the obvious thing to do.

But in our experience working with software development teams, the problem often isn't a lack of people. The problem is knowledge concentrated in too few people, unclear team roles, slow onboarding, or temporary demand.

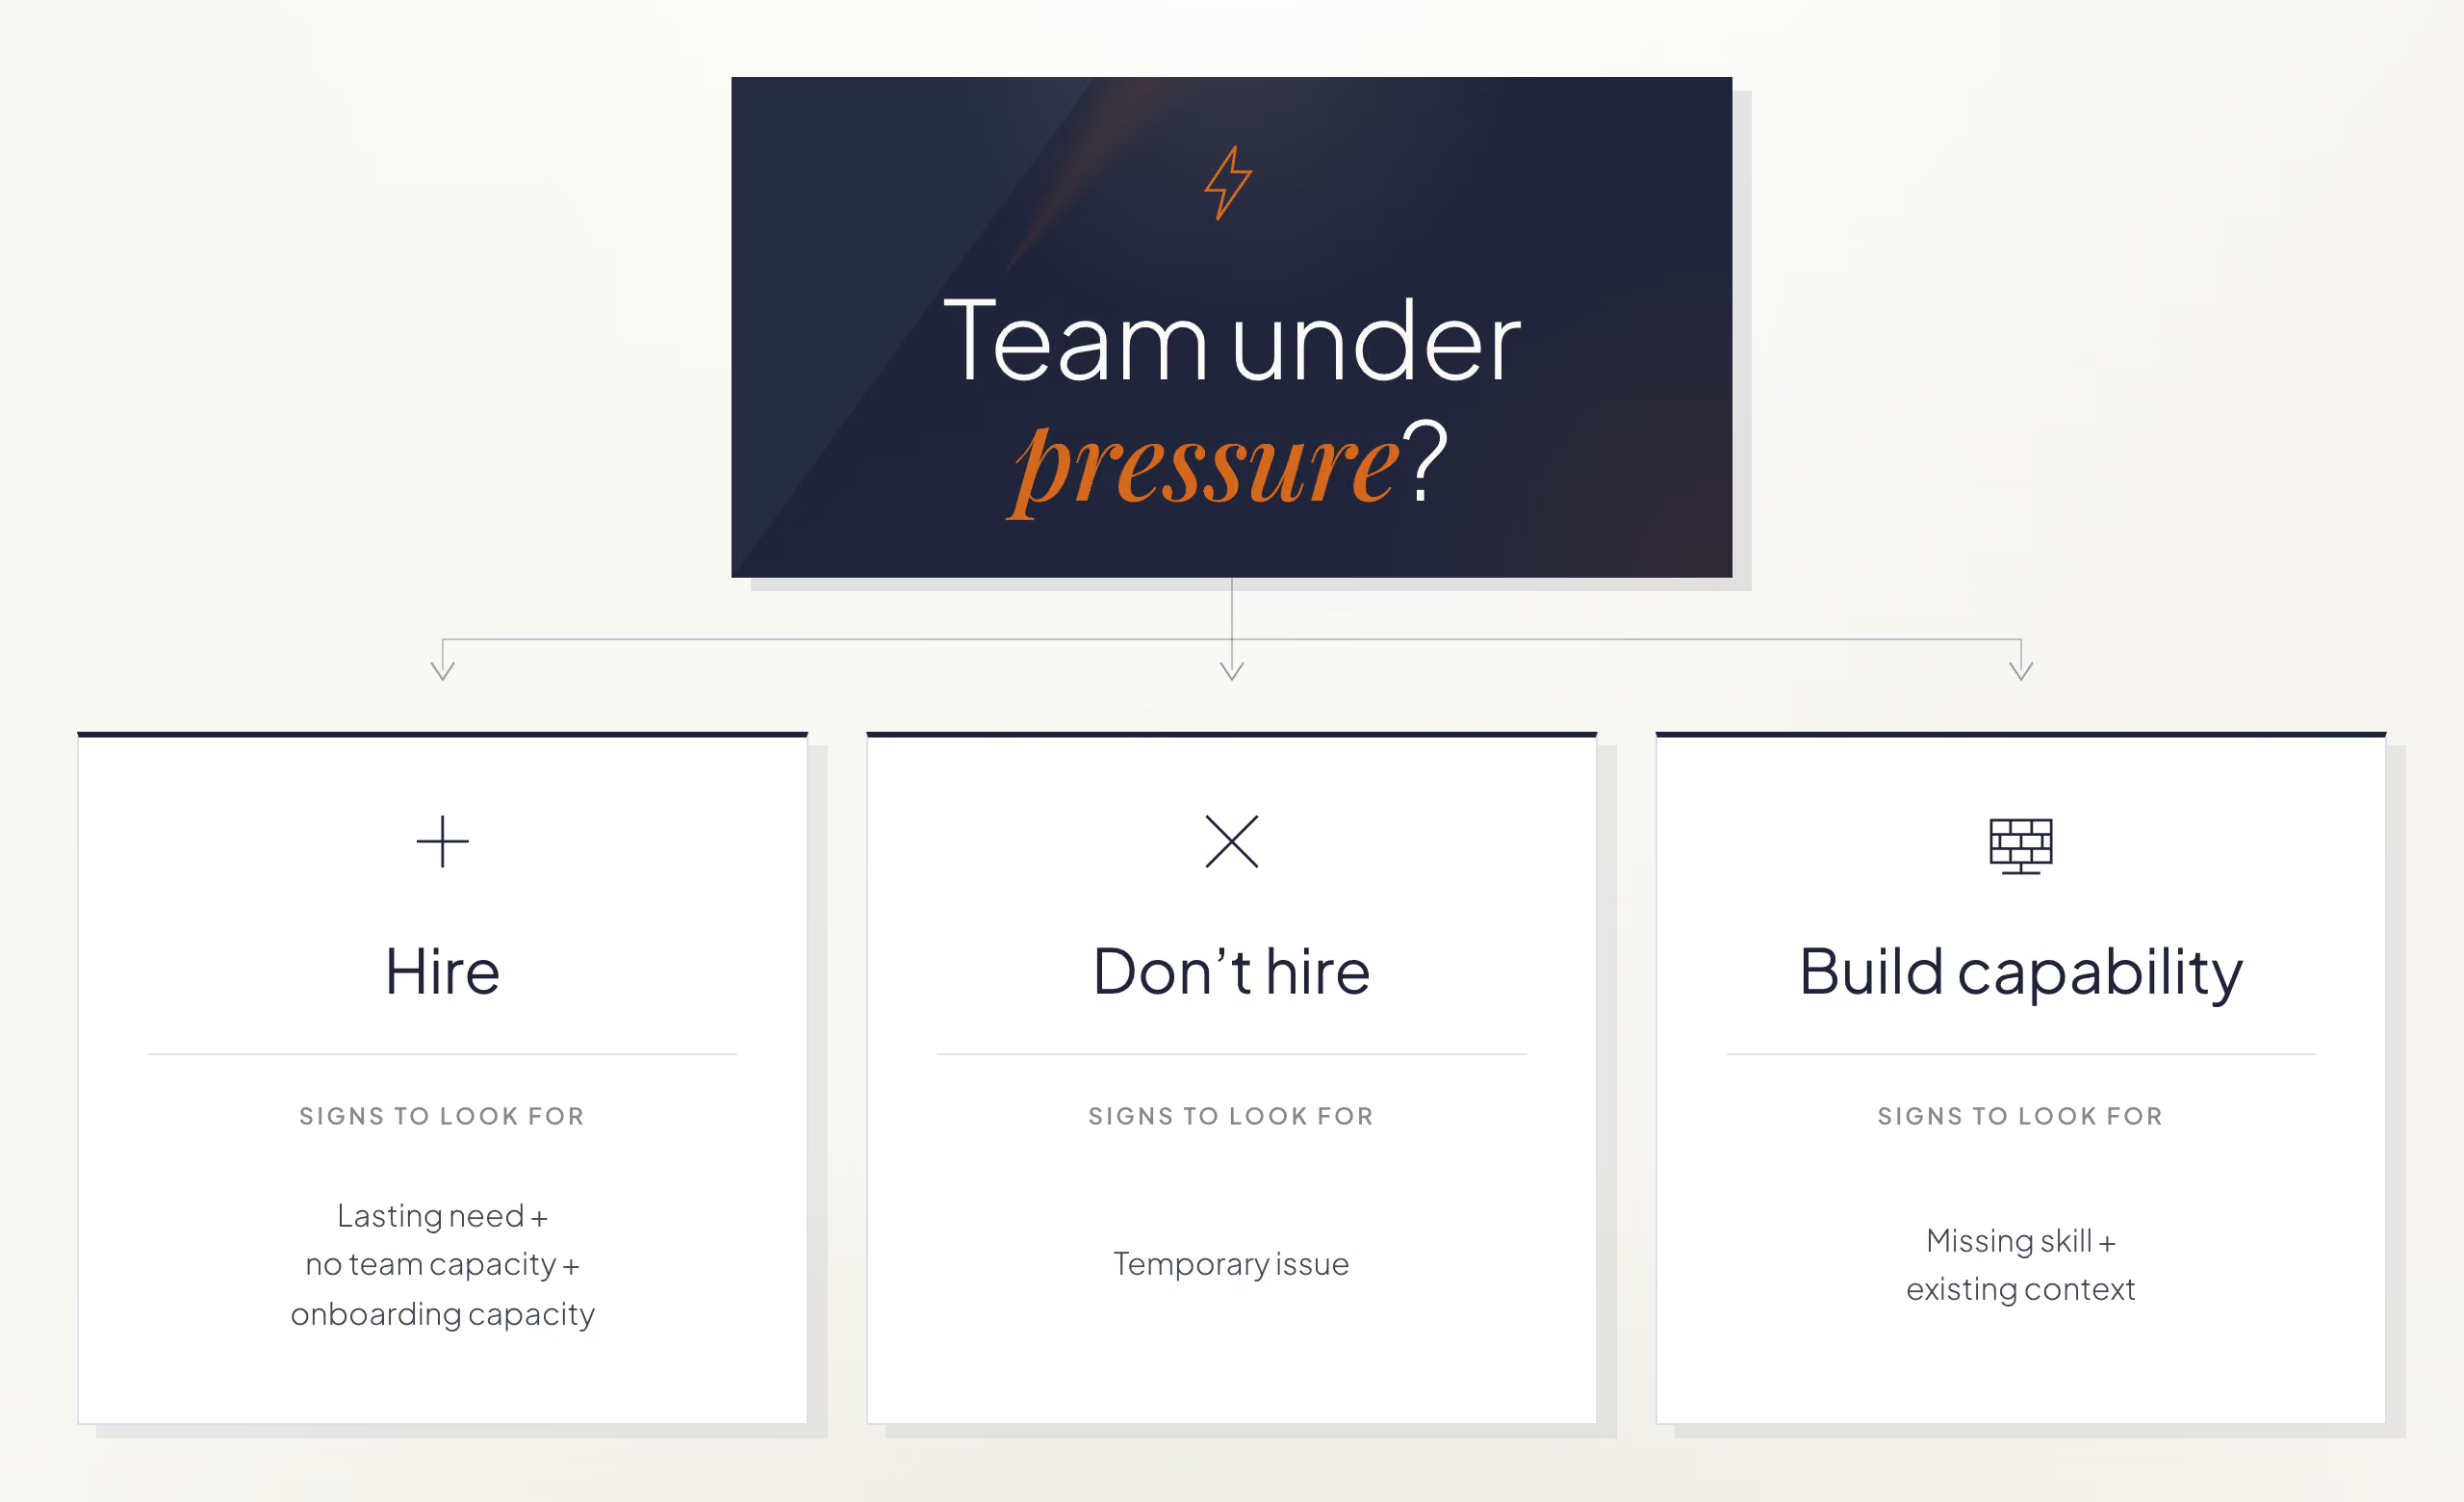
The question worth asking isn't who can fill the position, but what would help the team work better. That points to one of three answers: hire, don't hire, or build the capability from within. Figuring out which one applies, and why, is the real work before opening a search.

What you should ask before assuming you need someone new

Hiring works when three conditions are met: the need will last, no one on the team has the capacity to take it on, and the team can onboard someone well. That last condition is easy to overlook. A team can have a real, lasting gap and still not be ready to bring someone in if no one has the time to guide them.

The risk comes from jumping straight from "there's more work" to "we need someone" without checking what's causing the pressure. It's easy to turn a request into a list of requirements (X years of experience, a specific technology, advanced English) and start the search. The real cause is often something else: a project that grew too fast, a tech lead with no time to onboard new hires, processes that stopped scaling, or a team that lost key people and needs to recover knowledge before adding headcount.

That's why, before thinking about who could fill the role, we ask these questions:

  • What outcome is the client trying to achieve?
  • What's happening on that team today?
  • What specific problem is this hire meant to solve?
  • Does adding a person solve that problem?
  • Is there someone on the team who could take this on?
  • Are there other, less obvious alternatives?

When the answers confirm the need will last, the current team can't cover it, and the team has the capacity to onboard someone, hiring is the right call: opening the search fills a gap the team can't close internally.

Does the problem need someone new to fix it?

Not hiring is the right call when the problem behind the request is temporary, or when it will resolve before the new hire finishes onboarding. Recommending against a hire may sound unusual for a company that offers staff augmentation, but our job as a strategic partner is not to maximize every opportunity but to recommend the best decision for the client. Depending on what's actually going on, the fix can look like:

  • An internal rotation: moving someone with spare capacity into the gap.
  • Reorganizing responsibilities across the team instead of adding a seat.
  • Hiring a different profile than the one originally requested.
  • Combining two roles into one instead of opening two searches.
  • Waiting a few weeks, when the project context is about to change on its own.

Is a temporary increase in workload a good reason to hire?

This happened on a project with a long onboarding period. The initial request seemed clear: hire a mid-level developer. There was work and budget available. But when we spoke with the team, we found that the workload increased because one team member had been temporarily reassigned to another sub-team. Before moving forward, we considered what would happen when that person came back.

The client's system was complex: any new hire needed several months to understand the business, the architecture, and the platform before they could contribute independently.

The problem justifying the hire was going to disappear, but the new hire wouldn't. By the time that person had enough context, the need that started the search would no longer exist.

We recommended against moving forward, even though there was budget to add someone. The client avoided an unnecessary hire and months of onboarding for a problem that was already resolving itself. Sometimes the best answer is to wait a few weeks; other times, it's reorganizing the team or developing internal talent.

How can you build team capability without hiring?

Build capability internally when the team already has product context but lacks a specific skill. Developing that skill internally can be faster than waiting for someone new to reach the same level of context.

More people doesn't always mean more capacity. Onboarding a new hire takes time from the people already on the team: explaining the business and the architecture, reviewing their work, and building trust. That's why, during the first few weeks, a team can become less productive while it onboards someone new. Complex projects can include years of technical decisions and undocumented knowledge. New hires still need time to learn that context.

Should you hire a specialist or train someone on your team?

A client needed a senior SQL Server specialist. That niche skill set made the role difficult and expensive to fill. We started the search and interviewed candidates, but the deeper issue became clear quickly: the real challenge on the project wasn't SQL Server. It was understanding a product shaped by years of evolution, multiple applications, and complex business logic.

The right person to develop that expertise was already on the team. Instead of hiring someone with deep SQL Server expertise, the client supported that team member in building the SQL Server skills the project needed. That person had business knowledge, motivation, and a much shorter learning curve than an external hire would have had. An outside specialist provided targeted support when needed.

The team gained SQL Server expertise without losing months waiting for a new hire to learn the product first. The person who took on SQL Server gained a valuable new skill without stepping away from the other work they were doing on the project.

A team's capacity depends on how its people complement each other, what knowledge they share, and what autonomy they've developed, not just on headcount. A team of ten people who are aligned, with shared context and autonomy, can generate more value than a team of fifteen where much of the time goes into onboarding new hires.

Should you hire, wait, or develop the skill internally?

Scenario Signal What to do
Hire The need will last, no one on the team can cover it, and the team can onboard someone well Open the search for a clearly defined role
Don't hire The problem is temporary or resolves before onboarding finishes Wait, reorganize the team, or cover the gap another way
Build internal capability Missing specific expertise, not people; someone already has the business context Develop the skill internally, with targeted outside support if needed

What questions do we ask first?

  1. What specific problem are we trying to solve?
  2. Will the need still exist after the person has been hired and onboarded?
  3. Is there someone on the team who could cover it?
  4. Do we have the capacity to onboard someone well?
  5. Is the problem a lack of people, or is it caused by unclear roles, missing product knowledge, slow onboarding, or a temporary increase in workload?
  6. What impact will this hire have six months from now?
  7. If we couldn't hire today, what other option would we explore?
  8. What higher-priority work would someone on the team have to stop doing to cover this need?

Wait to open a search when the team can't define the problem, confirm the need will last, or support onboarding. Clarify those points first.

If you're weighing this decision with your own team, let's talk about whether to hire, reorganize, or develop someone already on the team.

llms.txt