Kaizen Teams

Dropdown

Table of Contents

Time to read

·

12

Published on

·

September 3, 2025

Last updated on

·

May 26, 2026

Vera Gonzalez, Frontend Developer at Kaizen Softworks

Vera Gonzalez

Too young to quit

Frontend Developer

AI

AI

How to Apply RAG Techniques to Boost Your AI Applications

Published on

·

May 27, 2026

Last updated on

·

May 26, 2026

Time to read

·

12

Vera Gonzalez, Frontend Developer at Kaizen Softworks

Vera Gonzalez

Frontend Developer

Large Language Models (LLMs) are powerful, but they come with two big limitations:

  • They don’t always have the most up-to-date knowledge.
  • They can only remember what fits in their context window.

Retrieval-Augmented Generation (RAG) solves this by connecting your LLM to an external knowledge base and retrieving relevant context before generating a response. (And yes… RAG also means “rag”, but here it’s definitely more high-tech than something you use to clean the kitchen 🧽).

1. What is RAG and how does it work?

Think of RAG as an assistant that searches first, then answers.

  1. The user sends a prompt.
  2. The system retrieves relevant information from a database.
  3. That information is added to the original prompt.
  4. The LLM generates the final answer.

Example: An HR chatbot could first retrieve the latest company policy document before answering questions about vacation days.

2. Retrieval techniques you can try

When it comes to finding the right information for your LLM, there are several approaches, each with its own strengths.

The most straightforward one is Keyword Search, where the system looks for exact or partial word matches in the text. This is simple, fast, and effective when you know the exact terminology to look for. For example, using BM25, you could pinpoint the exact paragraph in a technical manual that matches a user’s query.

Then there’s Semantic Search with Embeddings, which goes beyond exact matches to find text with the same meaning, even when the wording is different. This is particularly useful for cases like retrieving answers about “sick leave” even if the document calls it “medical absence.” By understanding synonyms and related concepts, semantic search adds a powerful layer of flexibility.

Finally, you can combine the best of both worlds with Hybrid Search. In this approach, the system runs both a keyword-based search (like BM25) and a semantic search (using embeddings) in parallel.

The results from each are then merged and re-ranked, often using techniques like Reciprocal Rank Fusion, so that documents highly ranked by either method can appear at the top.

This way, you capture exact matches for critical terms while also retrieving contextually relevant content that may be worded differently, making it especially powerful for cases like technical FAQs where precision and broader understanding both matter.

3. Improving your results

Even with a good retrieval strategy, not all results are equally useful. That’s where optimization techniques come in.

One of them is re-ranking with specialized models, such as cross-encoders. Instead of scoring the query and each document separately, cross-encoders process them together, allowing the model to understand fine-grained context and relationships between words. This produces more accurate relevance scores, ensuring the most useful documents appear first, even if they don’t share many exact keywords with the query.

Another useful approach is Metadata Filtering. By filtering results according to attributes like date, category, or document type, you can eliminate outdated or irrelevant information. Imagine narrowing your search to documents updated in the last six months – it’s a simple step that can drastically improve the quality of the information your system uses.

4. Preparing your data: the art of chunking

LLMs can’t process huge documents all at once. Chunking means splitting them into smaller pieces.

For example: Split a 100-page manual into 500-word sections with 10% overlap to ensure no important context gets lost.

Benefit: Improves retrieval relevance and accuracy.

5. Measure your performance

You can’t improve what you don’t measure.

Here’s two key metrics for RAG:

  • MAP (Mean Average Precision): How well relevant documents are ranked.
  • MRR (Mean Reciprocal Rank): How high the first relevant document appears.

Impact example: After optimizing, relevant documents moved from position #5 to #2, reducing search time for users.

6. What’s next for us at Kaizen?

The most exciting part is putting this knowledge into action.  

We see immediate opportunities to:

  • Boost the performance of chatbots for clients and internal tools.  
  • Experiment with hybrid retrieval to improve accuracy.  
  • Apply chunking strategies to make better use of large document sets.

Because in the end, whether it’s a rag for cleaning or RAG for AI, it’s all about wiping away the mess and delivering sharper results. 😉

Large Language Models (LLMs) are powerful, but they come with two big limitations:

  • They don’t always have the most up-to-date knowledge.
  • They can only remember what fits in their context window.

Retrieval-Augmented Generation (RAG) solves this by connecting your LLM to an external knowledge base and retrieving relevant context before generating a response. (And yes… RAG also means “rag”, but here it’s definitely more high-tech than something you use to clean the kitchen 🧽).

1. What is RAG and how does it work?

Think of RAG as an assistant that searches first, then answers.

  1. The user sends a prompt.
  2. The system retrieves relevant information from a database.
  3. That information is added to the original prompt.
  4. The LLM generates the final answer.

Example: An HR chatbot could first retrieve the latest company policy document before answering questions about vacation days.

2. Retrieval techniques you can try

When it comes to finding the right information for your LLM, there are several approaches, each with its own strengths.

The most straightforward one is Keyword Search, where the system looks for exact or partial word matches in the text. This is simple, fast, and effective when you know the exact terminology to look for. For example, using BM25, you could pinpoint the exact paragraph in a technical manual that matches a user’s query.

Then there’s Semantic Search with Embeddings, which goes beyond exact matches to find text with the same meaning, even when the wording is different. This is particularly useful for cases like retrieving answers about “sick leave” even if the document calls it “medical absence.” By understanding synonyms and related concepts, semantic search adds a powerful layer of flexibility.

Finally, you can combine the best of both worlds with Hybrid Search. In this approach, the system runs both a keyword-based search (like BM25) and a semantic search (using embeddings) in parallel.

The results from each are then merged and re-ranked, often using techniques like Reciprocal Rank Fusion, so that documents highly ranked by either method can appear at the top.

This way, you capture exact matches for critical terms while also retrieving contextually relevant content that may be worded differently, making it especially powerful for cases like technical FAQs where precision and broader understanding both matter.

3. Improving your results

Even with a good retrieval strategy, not all results are equally useful. That’s where optimization techniques come in.

One of them is re-ranking with specialized models, such as cross-encoders. Instead of scoring the query and each document separately, cross-encoders process them together, allowing the model to understand fine-grained context and relationships between words. This produces more accurate relevance scores, ensuring the most useful documents appear first, even if they don’t share many exact keywords with the query.

Another useful approach is Metadata Filtering. By filtering results according to attributes like date, category, or document type, you can eliminate outdated or irrelevant information. Imagine narrowing your search to documents updated in the last six months – it’s a simple step that can drastically improve the quality of the information your system uses.

4. Preparing your data: the art of chunking

LLMs can’t process huge documents all at once. Chunking means splitting them into smaller pieces.

For example: Split a 100-page manual into 500-word sections with 10% overlap to ensure no important context gets lost.

Benefit: Improves retrieval relevance and accuracy.

5. Measure your performance

You can’t improve what you don’t measure.

Here’s two key metrics for RAG:

  • MAP (Mean Average Precision): How well relevant documents are ranked.
  • MRR (Mean Reciprocal Rank): How high the first relevant document appears.

Impact example: After optimizing, relevant documents moved from position #5 to #2, reducing search time for users.

6. What’s next for us at Kaizen?

The most exciting part is putting this knowledge into action.  

We see immediate opportunities to:

  • Boost the performance of chatbots for clients and internal tools.  
  • Experiment with hybrid retrieval to improve accuracy.  
  • Apply chunking strategies to make better use of large document sets.

Because in the end, whether it’s a rag for cleaning or RAG for AI, it’s all about wiping away the mess and delivering sharper results. 😉

Related Articles

View all articles

·

Aug 28, 2026

About Catalyst 26: Partnerships & Ecosystem Conference

Everything to know about Catalyst 26: dates, price, who attends, both keynote recaps, and when the next Catalyst event is.

12 read time

Read more

Catalyst 26 was Partnership Leaders' fifth annual conference for partnership, ecosystem, and go-to-market professionals. It took place August 25 and 26, 2026, at the Marriott Hotel at the Brooklyn Bridge in New York, with more than 1,000 attendees and 70-plus speakers from companies including Anthropic, OpenAI, Google, Microsoft, IBM, BCG, and Siemens.

Dates August 25–26, 2026
Location Marriott Hotel at the Brooklyn Bridge, Brooklyn, NY
Edition 5th annual
Attendees 1,000+ partnership, ecosystem, and GTM professionals
Speakers 70+, including people from Anthropic, OpenAI, Google, Microsoft, IBM, BCG, and Siemens.
Price $849 early bird, rising to $999, then $1,999

Who Catalyst events are for

Catalyst brought together people building and running partner programs across SaaS, AI, consulting, systems integration, agencies, and major cloud platforms.

Attendees included executives leading partnership organizations, and people working directly in alliances, partner sales, marketing, operations, strategy, and enablement.

What Catalyst 26 is like

You can look at the agenda before a conference and have a pretty good idea of what you'll find. Being there is different.

This year's theme was "Navigating Frontier Ecosystems". Anthropic's Head of Partnerships and one of OpenAI's partner program leads appeared on the same agenda as people from Oracle, Siemens, IBM, and BCG, companies that have run formal partner programs for two decades.

That mix was one of the most interesting parts of the conference. Newer AI companies were discussing partner tiers, co-selling, and joint delivery alongside companies where those models have been part of their business for years.

What Catalyst 26 covered

Catalyst 26 split its sessions into eight pillars:

  • Advancing Organizational Maturity: turning partnerships into something measured and repeatable instead of one founder doing favors for another.
  • Become a Strategic Partner: getting partnerships involved when product and business decisions are made, not told about them afterward.
  • Frontier Partner Experience: adapting partner programs as AI changes how companies build and integrate products.
  • Path to CPO: career sessions for people aiming to lead partnerships at the executive level.
  • Co-Build: two companies building something together.
  • Co-Market: two companies running a campaign together.
  • Co-Sell: two sales teams working the same deal.
  • Co-Serve: two companies delivering the same engagement to a client.

Catalyst 26 sessions

Day 1 Keynote

The Day 1 keynote brought together Partnership Leaders’ CEO Asher Mathew, Tribe AI’s Co-founder & CEO Jaclyn Rice Nelson, Anthropic’s Head of Partnerships Phil Samenuk, and Boomi’s Chairman & CEO Steve Lucas.

Their discussion focused on how companies are relying on partners to build, sell, and deliver products across AI, cloud, and enterprise software. A few points stood out:

  • More companies have dedicated partner teams now, which means a generic, one-size-fits-all partner program doesn't cut it anymore. Partners show up when the program fits how they work.
  • New AI products and cloud services are shipping so fast that a partner program can't just get set once and left alone. Incentives, support, and how you work together need regular updates.
  • Partnerships also came up as a way to access data a company couldn’t reach on its own, whether that meant getting access to it, combining it, or putting it to use.
  • AI doesn't change the basics of a good partnership. Account planning, clear ownership, and relationships built over time still matter most.

Day 2 Keynote

The Day 2 keynote featured Ramp’s Lead Economist Ara Kharazian, Eliza’s Founder Brian Benedict, Siemens’ EVP Global Partner Ecosystem Dion Smith, and Oracle’s SVP, Partner Sales & Operations Strategy Leah Yomtovian.

A few points stood out:

  • The spending data told a slower story than expected: AI adoption is mostly going toward productivity gains and task automation, not some overnight shift.
  • Siemens is in the middle of folding more than 68,000 partners and roughly 200 separate programs into a single global one, mainly to make it easier to coordinate across IT and operational technology.
  • Oracle's approach is a running "listening tour": every partner gets the same baseline benefits, then incentives and credits get layered based on the type of partner and how they work with Oracle.
  • There was also talk of a newer kind of service team: bring in engineers, turn AI requirements into working products, and reuse delivery methods that already work instead of starting from scratch each time.

Next Catalyst events

The date and location of Catalyst 27 hasn’t been announced yet. In the meantime, you can check out the half-day Catalyst Summits in different cities:

  • October 20, 2026 - Seattle
  • October 27, 2026 - Chicago
  • October 2026 - Los Angeles
  • December 2026 - Singapore

Check Partnership Leaders’ events page for updates.
·

Aug 26, 2026

Why adding people doesn't always fix a struggling team

Learn when a software team should hire, wait, reorganize, or build skills internally, and how to tell which option will actually help.

12 read time

Read more

When a client asks to hire someone new, a common reaction is to open a search. There's more work, more pressure, and new features to build. It seems like the obvious thing to do.

But in our experience working with software development teams, the problem often isn't a lack of people. The problem is knowledge concentrated in too few people, unclear team roles, slow onboarding, or temporary demand.

The question worth asking isn't who can fill the position, but what would help the team work better. That points to one of three answers: hire, don't hire, or build the capability from within. Figuring out which one applies, and why, is the real work before opening a search.

What you should ask before assuming you need someone new

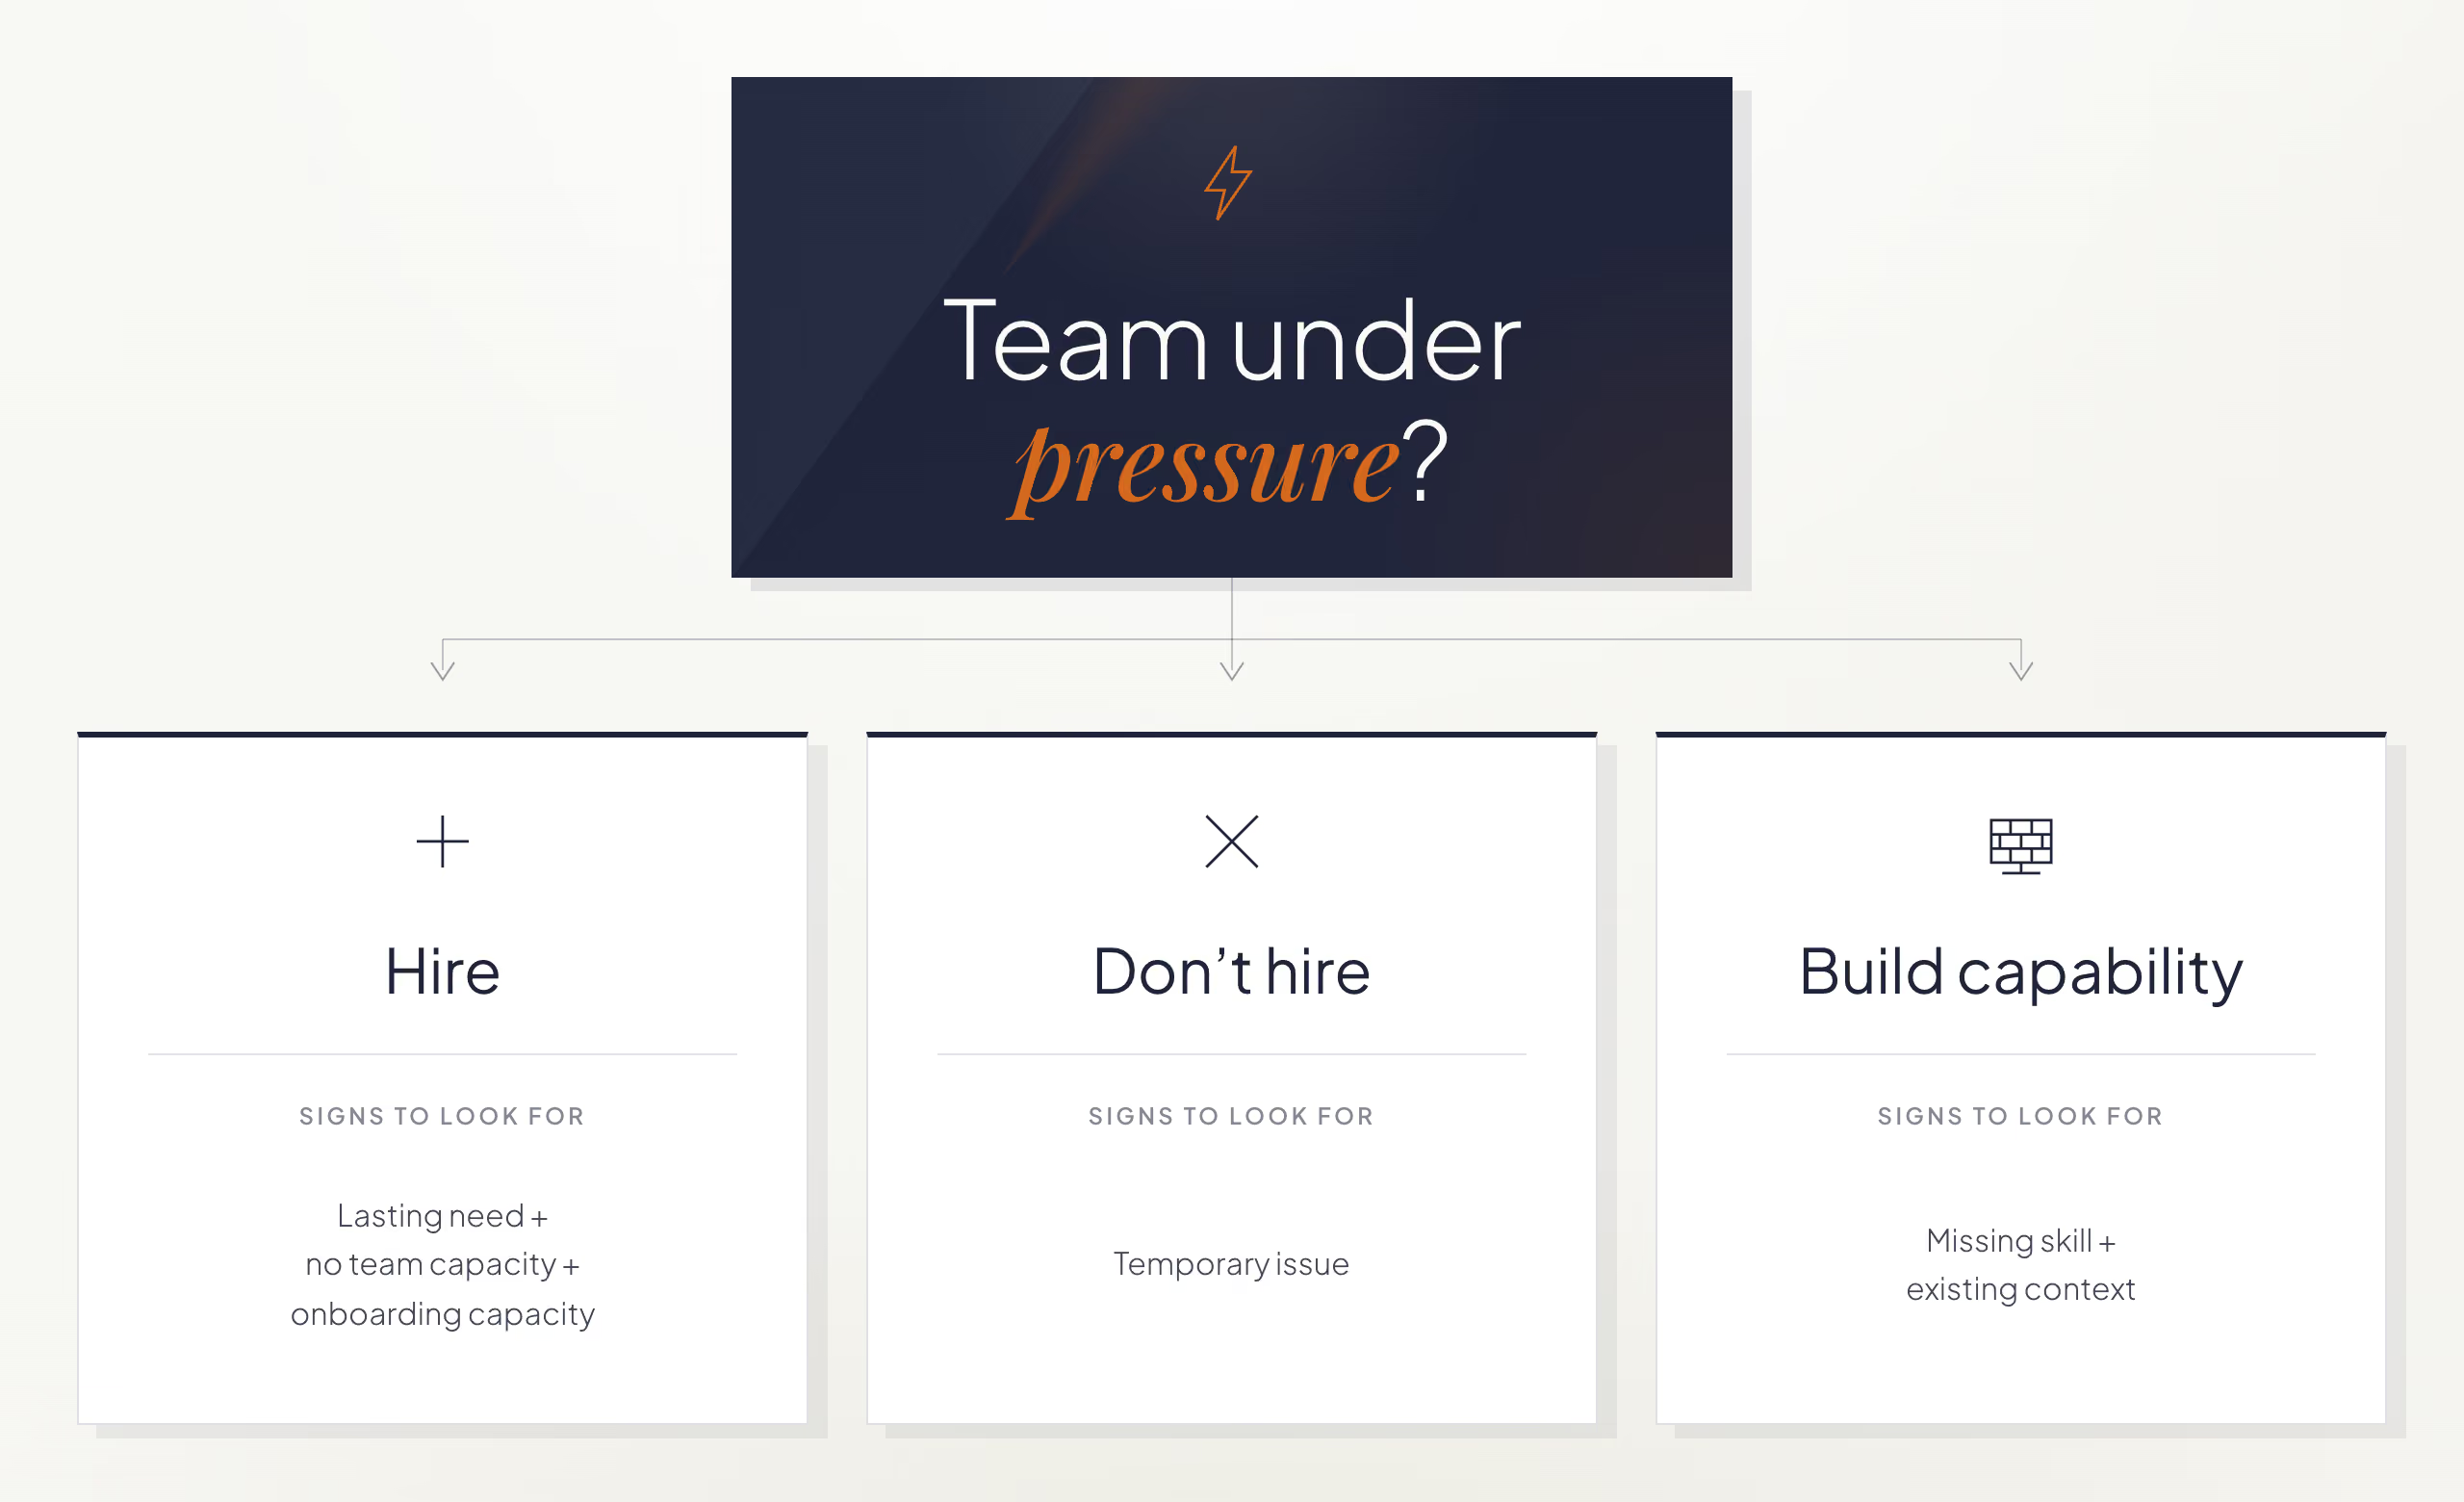
Hiring works when three conditions are met: the need will last, no one on the team has the capacity to take it on, and the team can onboard someone well. That last condition is easy to overlook. A team can have a real, lasting gap and still not be ready to bring someone in if no one has the time to guide them.

The risk comes from jumping straight from "there's more work" to "we need someone" without checking what's causing the pressure. It's easy to turn a request into a list of requirements (X years of experience, a specific technology, advanced English) and start the search. The real cause is often something else: a project that grew too fast, a tech lead with no time to onboard new hires, processes that stopped scaling, or a team that lost key people and needs to recover knowledge before adding headcount.

That's why, before thinking about who could fill the role, we ask these questions:

  • What outcome is the client trying to achieve?
  • What's happening on that team today?
  • What specific problem is this hire meant to solve?
  • Does adding a person solve that problem?
  • Is there someone on the team who could take this on?
  • Are there other, less obvious alternatives?

When the answers confirm the need will last, the current team can't cover it, and the team has the capacity to onboard someone, hiring is the right call: opening the search fills a gap the team can't close internally.

Does the problem need someone new to fix it?

Not hiring is the right call when the problem behind the request is temporary, or when it will resolve before the new hire finishes onboarding. Recommending against a hire may sound unusual for a company that offers staff augmentation, but our job as a strategic partner is not to maximize every opportunity but to recommend the best decision for the client. Depending on what's actually going on, the fix can look like:

  • An internal rotation: moving someone with spare capacity into the gap.
  • Reorganizing responsibilities across the team instead of adding a seat.
  • Hiring a different profile than the one originally requested.
  • Combining two roles into one instead of opening two searches.
  • Waiting a few weeks, when the project context is about to change on its own.

Is a temporary increase in workload a good reason to hire?

This happened on a project with a long onboarding period. The initial request seemed clear: hire a mid-level developer. There was work and budget available. But when we spoke with the team, we found that the workload increased because one team member had been temporarily reassigned to another sub-team. Before moving forward, we considered what would happen when that person came back.

The client's system was complex: any new hire needed several months to understand the business, the architecture, and the platform before they could contribute independently.

The problem justifying the hire was going to disappear, but the new hire wouldn't. By the time that person had enough context, the need that started the search would no longer exist.

We recommended against moving forward, even though there was budget to add someone. The client avoided an unnecessary hire and months of onboarding for a problem that was already resolving itself. Sometimes the best answer is to wait a few weeks; other times, it's reorganizing the team or developing internal talent.

How can you build team capability without hiring?

Build capability internally when the team already has product context but lacks a specific skill. Developing that skill internally can be faster than waiting for someone new to reach the same level of context.

More people doesn't always mean more capacity. Onboarding a new hire takes time from the people already on the team: explaining the business and the architecture, reviewing their work, and building trust. That's why, during the first few weeks, a team can become less productive while it onboards someone new. Complex projects can include years of technical decisions and undocumented knowledge. New hires still need time to learn that context.

Should you hire a specialist or train someone on your team?

A client needed a senior SQL Server specialist. That niche skill set made the role difficult and expensive to fill. We started the search and interviewed candidates, but the deeper issue became clear quickly: the real challenge on the project wasn't SQL Server. It was understanding a product shaped by years of evolution, multiple applications, and complex business logic.

The right person to develop that expertise was already on the team. Instead of hiring someone with deep SQL Server expertise, the client supported that team member in building the SQL Server skills the project needed. That person had business knowledge, motivation, and a much shorter learning curve than an external hire would have had. An outside specialist provided targeted support when needed.

The team gained SQL Server expertise without losing months waiting for a new hire to learn the product first. The person who took on SQL Server gained a valuable new skill without stepping away from the other work they were doing on the project.

A team's capacity depends on how its people complement each other, what knowledge they share, and what autonomy they've developed, not just on headcount. A team of ten people who are aligned, with shared context and autonomy, can generate more value than a team of fifteen where much of the time goes into onboarding new hires.

Should you hire, wait, or develop the skill internally?

Scenario Signal What to do
Hire The need will last, no one on the team can cover it, and the team can onboard someone well Open the search for a clearly defined role
Don't hire The problem is temporary or resolves before onboarding finishes Wait, reorganize the team, or cover the gap another way
Build internal capability Missing specific expertise, not people; someone already has the business context Develop the skill internally, with targeted outside support if needed

What questions do we ask first?

  1. What specific problem are we trying to solve?
  2. Will the need still exist after the person has been hired and onboarded?
  3. Is there someone on the team who could cover it?
  4. Do we have the capacity to onboard someone well?
  5. Is the problem a lack of people, or is it caused by unclear roles, missing product knowledge, slow onboarding, or a temporary increase in workload?
  6. What impact will this hire have six months from now?
  7. If we couldn't hire today, what other option would we explore?
  8. What higher-priority work would someone on the team have to stop doing to cover this need?

Wait to open a search when the team can't define the problem, confirm the need will last, or support onboarding. Clarify those points first.

If you're weighing this decision with your own team, let's talk about whether to hire, reorganize, or develop someone already on the team.

llms.txt