Kaizen Teams

Dropdown
Dropdown arrow for the table of contents.

Table of Contents

Clock icon for reading time.
Time to read

·

12

Calendar icon for the publish date.
Published on

·

January 21, 2026

Refresh icon for the last updated date.
Last updated on

·

August 27, 2026

Franco Possamay, Full-Stack Developer at Kaizen Softworks

Franco Possamay

LinkedIn icon.

Peñarol football fan

Full-Stack Developer

About Us

About Us

Code review culture: the team is our safety net

Calendar icon for the publish date.
Published on

·

August 27, 2026

Refresh icon for the last updated date.
Last updated on

·

August 27, 2026

Clock icon for reading time.
Time to read

·

12

Franco Possamay, Full-Stack Developer at Kaizen Softworks

Franco Possamay

LinkedIn icon.

Full-Stack Developer

At Kaizen, we don’t believe software quality is enforced by a checklist or a single gatekeeper. It’s something we build together, day in and day out, as a team.

We’ve been working on this platform for years. What started with two developers has grown into a 30+ person team building a large-scale logistics system. And like any growing team, we faced a big question:

How do you keep quality high without turning into a slow, over-regulated machine?

We chose trust over set in stone rules. And in doing so, we learned something simple but powerful: Our strongest safety net isn’t a process. It’s each other.

A Team That Catches Each Other

When systems get complex, legacy code, multiple teams, tight deadlines, it’s tempting to respond with more rules. But heavy oversight kills initiative. Instead of building a team that takes ownership, you get one that’s just trying not to mess up.

We took a different approach. We built a system where quality doesn’t rest on one person, it’s shared, distributed, and reinforced by the people around you.

Code review is just one part of that system, but it’s where this mindset comes to life.

​​Code Review as a Conversation

For us, code review isn’t about nitpicking, it’s a technical conversation between teammates.

When I open a PR, I’m not bracing for criticism. I’m inviting collaboration. Together, we’re asking: “Are we solving this clearly, cleanly, and in a way that makes life easier for the next person?”

Code reviews are done by other developers from the same sub-project. That means the person reviewing already has context, and because the reviewer role rotates, everyone gets to both give and receive feedback. It’s collaborative by design, and part of how we grow as a unit.

We review with a few key principles in mind:

  • Clarity over cleverness: Can someone new understand this without a full-day walkthrough?

  • Don’t reinvent the wheel: Are we duplicating logic that already exists? If so, we flag it and refactor.

  • Performance with perspective: Are we making smart decisions, like reducing unnecessary database calls?

We refer to our internal Wiki often, not as a rulebook, but as a shared language.

Ownership Starts with One, Backed by All

One of our core beliefs:
“Ownership starts with the person who says it’s done, but quality is everyone’s job.”

We say it often: “The ownership falls mainly on the person who tests it and says it’s okay.”

It’s not about blame. It’s about trusting each dev to be accountable, knowing the team has their back. That shared responsibility creates a culture where people step up, not out of fear, but because they’re supported.

What Happens When Something Slips?

Let’s be honest: we’re human. Not every issue gets caught in review. But that doesn’t break our system, it proves why it works.

Because someone else will catch it later. And when they do, they won’t ignore it, they’ll flag it, fix it, and keep moving.

We log cleanup tasks in our tech debt backlog. It’s not a black hole, it’s a to-do list for continuous improvement. A way to keep tightening the net.

Reviews Are Where We Grow

In our team, code review it’s where learning happens.

New devs get real-time, contextual feedback. Seniors reflect on their habits. We share ideas, challenge each other, and improve as a unit. It’s ongoing, hands-on knowledge transfer, baked into the flow of work.

We don’t trust the code because it’s perfect. We trust it because of how it’s built:
by a team that shows up, collaborates, and looks out for each other.

In the End, It’s the Team

Our confidence doesn’t come from tools or top-down rules. It comes from people who care. People who ask questions, challenge decisions, and leave the codebase better than they found it.

The team is the system. The team is the process. The team is the safety net.
And when that’s in place, you can scale without fear.

Related Articles

View all articles

·

Oct 23, 2026

How to build high-fidelity prototypes with AI

How a design system lets Marketing and Product teams use AI to build on-brand prototypes, based on Kaizen’s own experience and turnaround numbers.

Clock icon for reading time.

12 read time

Read more

AI makes it easier for more people across a company to create a first visual version without relying on Design for every step.

Marketing can generate campaign assets. Product managers can turn ideas into prototypes. Teams can make an idea visible earlier in the process.

That creates a new design problem.

If more people can create, how do you make sure the output still reflects the decisions Design has already made about hierarchy, typography, spacing, composition, and brand?

A design system can help.

When its rules, components, templates, and examples are available to AI tools, other teams can create within boundaries Design has already defined.

Design does not have to build every first version. It can focus on reviewing important decisions and improving the system when recurring problems appear.

A design system can carry judgment beyond the Design team

A design system gives teams shared rules for creating consistent work.

It can define:

  • Color, typography, spacing, and composition.
  • Components and how they behave.
  • Templates for recurring layouts.
  • Examples that show how those decisions work together.

That context is useful for AI too.

Without it, someone creating a page, presentation, or social post has to explain what “on brand” or “well designed” means in a prompt.

With a design system, many of those decisions are already documented. AI has a reference for how content should be structured, which components belong together, and what kinds of compositions fit the brand.

Teams get a starting point that is closer to the company’s existing visual language without having to describe it from scratch.

What this can look like across teams

Marketing can create recurring assets with less production dependency
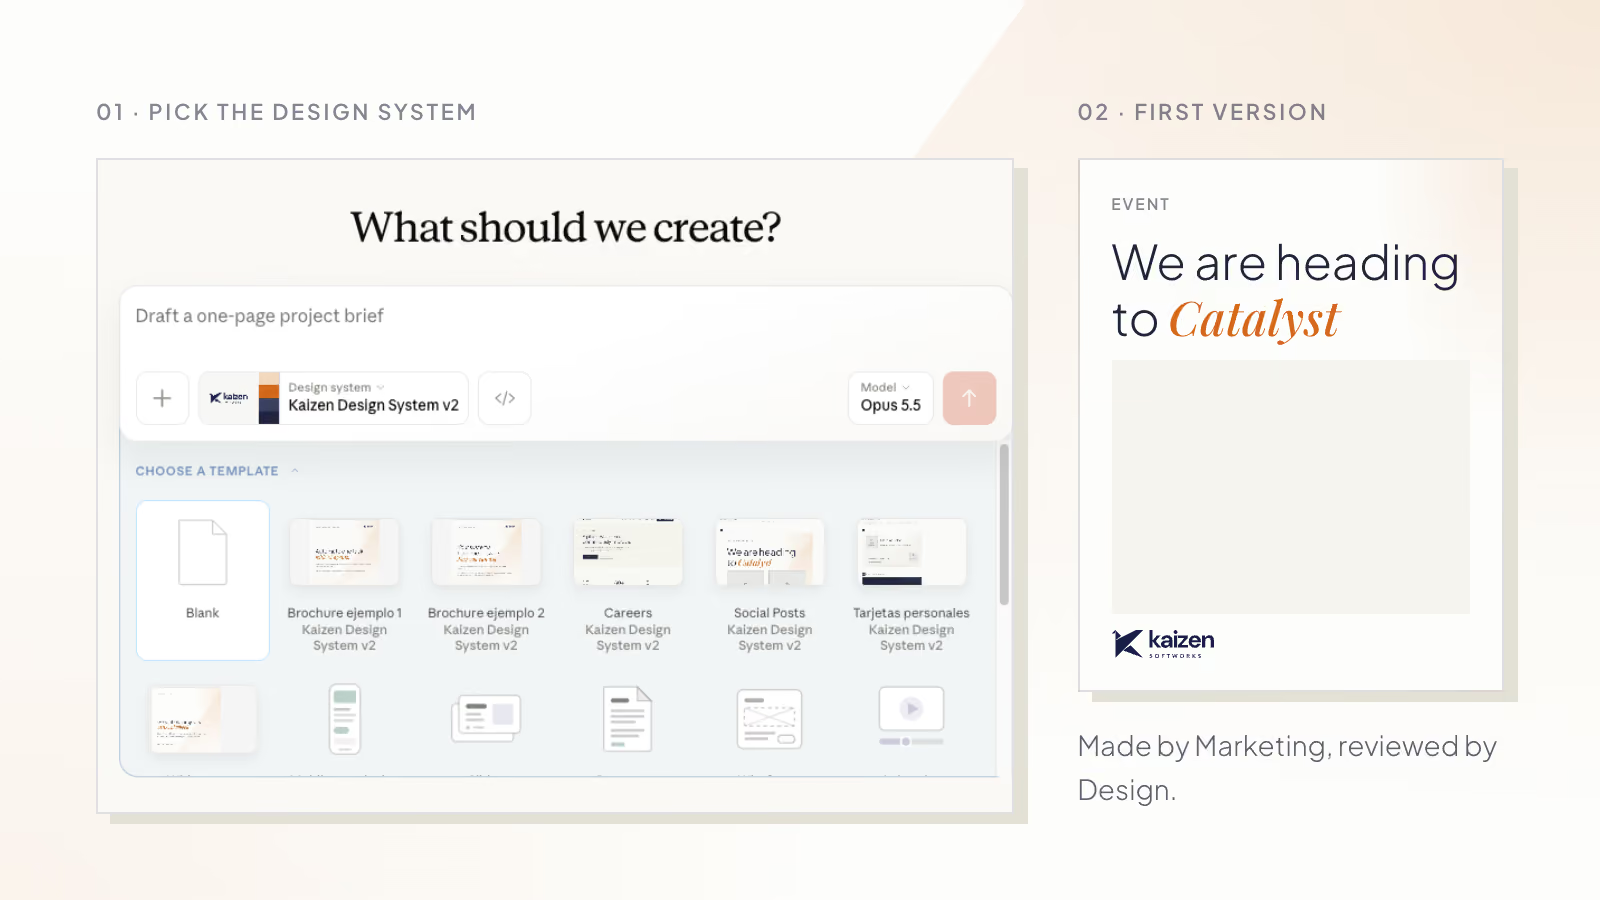
Marketing often works with recurring formats such as social posts, campaign pages, and event assets.

Templates can give the team enough structure to create a usable first version independently. A social template, for example, can define typography, spacing, image treatment, and composition while leaving room for the content to change.

Design can then focus its review on the decisions that need attention.

Product teams can make ideas visible earlier
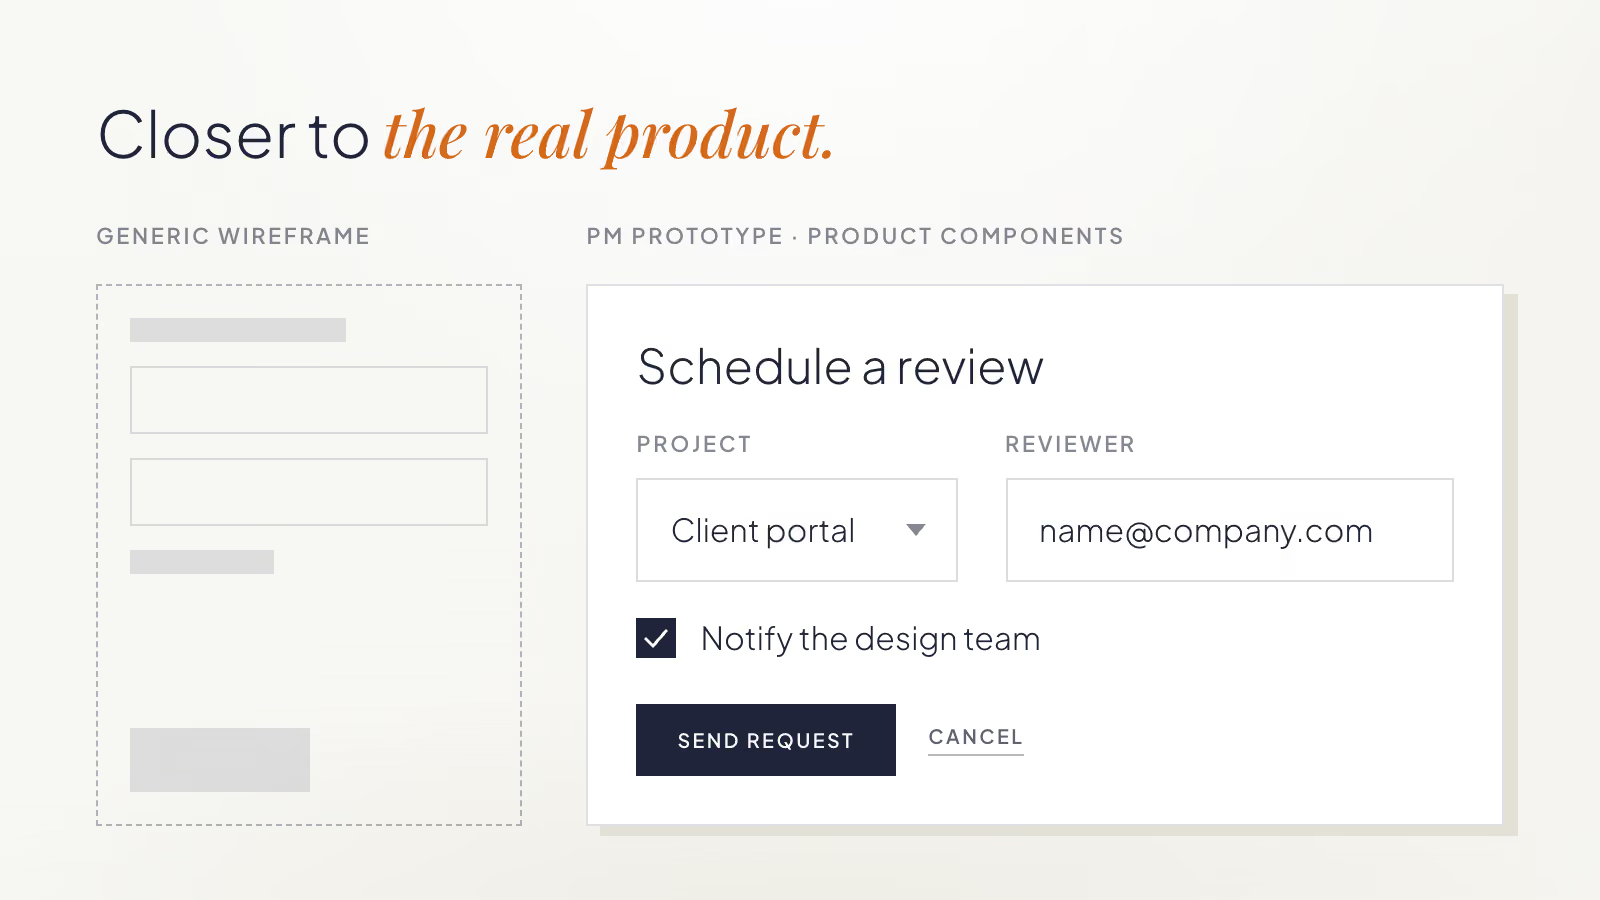
Product managers often need something visual before they need production-ready design.

If an AI tool has access to the same components and rules the product already uses, a PM can create a rough prototype that is closer to the real product than a generic wireframe.

The prototype is not a design direction by itself. It gives Product and Design something concrete to discuss.

Instead of spending time explaining what an idea might look like, they can focus on whether the flow makes sense, what needs to change, and where deeper design work is needed.

Generated work can show where the system is weak

AI does not only use the design system. Its output can also reveal where the system needs more guidance.

We saw this while using our own design system with AI at Kaizen.

Our Design team created the system while redesigning the Kaizen website. It documented the site’s colors, typography, composition rules, components, and templates. Marketing later began using that same system with AI to create website prototypes and social content.

One pattern kept appearing.

The AI put almost everything inside boxes.

Text, images, and entire sections appeared inside containers, even when a more open composition would have worked better.

Design reviewed the source material and found that many of the examples and rules leaned toward contained compositions. The AI was reproducing the patterns it had been given.

The team added guidance and examples for other layout approaches. The generated work became more varied and used more open compositions.

Instead of correcting the same problem in each new asset, the team improved the guidance that influenced future outputs.

That is one of the useful side effects of this process: recurring corrections can point to gaps in the system itself.

Autonomy still needs boundaries

Giving more people the ability to create does not mean every deliverable should follow the same workflow.

A recurring social post built from an established template may only need a quick review. A new product workflow may need much more involvement from Product and Design before anyone treats the prototype as a direction.

Teams can start by agreeing on three things:

What can teams create independently?

Identify recurring formats where the main design decisions are already understood.

What needs Design review?

Decide which outputs need a light check and which need deeper involvement.

What should go back into the system?

When the same correction happens repeatedly, update the shared rule, component, template, or example.

These boundaries make it clear where teams can move independently and where Design’s judgment is still needed.

What this changed for us at Kaizen

Before introducing this process, a LinkedIn visual could take more than two weeks from request to delivery once other priorities, coordination, review, and revisions were included.

We now estimate that a similar piece can move from copy to something ready to publish in about one afternoon.

For website work, a process that previously took around two weeks can now start with a Marketing-generated prototype in about two days, followed by roughly two days of Design refinement and production.

These are elapsed turnaround estimates, not active design hours. Reusable templates, the design system, clearer responsibilities, and the review process all contribute to the difference.

The biggest change is where the work starts.

Marketing can reach a concrete first version sooner. Design can spend more time refining important decisions and improving the system that will influence the next piece too.

For teams exploring this approach, start with one repeatable format.

Define the rules, examples, and templates needed to create a reasonable first version. Agree on where Design should enter the process. Then pay attention to recurring corrections.

If the same typography, layout, or composition problem keeps appearing, improve the shared guidance instead of fixing the same issue every time.

The goal is to make Design’s decisions reusable while keeping Design involved where its judgment matters most.

If you are working through the same questions, we can help you turn your existing design decisions into practical rules, templates, and review workflows your teams can use with AI.
‍

·

Oct 21, 2026

How to modernize legacy software without disrupting daily operations

How to modernize legacy software without disrupting daily operations: migration strategy, defining requirements, user validation, and where AI actually helps.

Clock icon for reading time.

12 read time

Read more

Legacy software does not become a problem just because it is old.

It becomes a problem when it starts limiting the business.

In one of our modernization projects, a legacy application was still central to the client's product. Customers used it every day to search and book flights, hotels, transportation, and other travel services.

But maintaining it had become expensive. Routine changes took too long, the technology was no longer supported, and the application struggled to meet current accessibility, usability, and security requirements.

The company needed to replace it without interrupting the customers who depended on it.

There is no single right way to modernize legacy software. The right approach depends on how the system works, how users depend on it, and what it will cost to run the old and new systems during the transition.

TLDR

  • Modernize when the existing system is creating business problems, not simply because the technology is old.
  • Compare incremental migration with building the replacement separately.
  • Treat legacy code as a reference, not the specification.
  • Define scope, expected behavior, and acceptance criteria clearly.
  • Validate the replacement with real users before broad migration.
  • Treat launching the new system and retiring the old one as separate milestones.
  • AI can speed up implementation, but it cannot resolve unclear requirements.

Start with the business problem

An old system may still serve the business well.

Modernization becomes more urgent when maintaining it starts getting in the way of what the company needs to do.

Common signs include:

  • Routine changes taking too much engineering time.
  • Security or compliance requirements becoming harder to meet.
  • Integrations becoming difficult to maintain.
  • Customer requests becoming expensive to deliver.
  • Teams avoiding necessary changes because they fear breaking the system.

These problems give the modernization a purpose.

Instead of asking, “How do we rebuild this application in newer technology?”, ask:

What constraints does the replacement need to remove?

That question helps keep the project focused on business needs rather than technology for its own sake.

Decide how the old and new systems will coexist

One of the first decisions is whether to migrate gradually or build the replacement separately.

An incremental migration can work well when parts of the system can move independently. But it also means the old and new applications may need to work together for months.

That temporary architecture has a cost.

In this project, the team initially considered releasing parts of the replacement while the rest of the product remained in the legacy application. They even started working that way.

But the approach introduced additional complexity. Each new feature needed to work alongside the legacy system, requiring compatibility, security, and interoperability work that would eventually have to be removed. With tight deadlines, the extra development effort and future maintenance costs made this approach impractical.

The team decided to build the replacement separately while keeping the legacy application in production. Once the new application was ready, selected customers began using it and reporting issues or missing functionality before the broader migration.

In other projects, moving functionality gradually has made more sense because workflows could be separated cleanly.

The useful question is:

What temporary work does each migration strategy create?

If gradual migration requires months of disposable compatibility work, a separate replacement may be easier to control. If capabilities can move independently, incremental migration may reduce risk.

Make that trade-off explicit before development starts.

Treat legacy code as evidence, not the specification

One of the hardest questions in a modernization is simple:

What should the new system actually do?

“Make it work like the old system” is not enough.

Legacy code can show developers how something was implemented. It cannot always explain which behaviors still matter, why exceptions exist, or what users depend on today.

For each piece of work, define:

  • The scope.
  • The expected behavior.
  • Acceptance criteria.
  • Representative use cases or test cases.

Instead of writing:

“Recreate the functionality from the legacy application.”

Start by defining what the user needs to accomplish. Then describe the steps they take, what information they need to see, how the application should respond, and how the team will verify that the feature works as expected.

Modernization projects will uncover missing details. When they do, make the new work visible instead of quietly expanding the task already in progress.

Protect the team's capacity

Keeping the legacy system running while building its replacement creates two workloads.

Production support can quickly compete with modernization work, especially when the same engineers understand both systems.

Before committing to a schedule, decide:

  • Who supports the legacy application?
  • Which legacy improvements still need to happen?
  • Which requests can wait?
  • How much modernization capacity is protected?
  • What happens when a production issue interrupts the plan?

A deadline is more useful when the capacity behind it is clear.

Validate the replacement with real users

Development being complete does not mean the migration is complete.

Before moving everyone, selected customers on this project used the replacement in their real workflows.

They found bugs, missing information, and behaviors the development team had not anticipated.

Technical completeness does not guarantee that users can complete their work.

Before broad rollout, test realistic tasks with real users. Find out where information is missing, which workflows break down, and where people still need the old system.

Separate launch from legacy shutdown

A migration rarely happens in one event.

The replacement may already be serving customers while the team continues fixing gaps and moving the remaining users.

Treat these as separate milestones:

  1. The replacement is ready for testing.
  2. The replacement is ready for production users.
  3. Customers no longer depend on the legacy system.

Before retiring the old application, confirm that users can complete their important workflows, support teams can resolve problems in the new system, and customers no longer need to return to the legacy application.

If users keep going back, find out why.

The replacement may be missing functionality, require more training, or make an existing task harder.

Migration success is not simply having the new application in production.

It is reaching the point where people can stop depending on the old one.

AI makes clear requirements more important

AI was introduced partway through this modernization project and helped the team implement work faster.

It worked best when the task was already clear.

With defined scope, acceptance criteria, and test cases, developers could use AI to produce more of the implementation and spend more time reviewing the code and checking the expected behavior.

Ambiguous requirements stayed ambiguous.

AI can reduce the effort required to produce code. It cannot decide which legacy behavior matters or what the replacement should do.

As implementation gets faster, understanding the system and defining the work become even more important.

Plan the migration, not just the deadline

A delivery date is not a migration plan.

Teams also need to understand:

  • Which pieces of work depend on each other.
  • What can happen in parallel.
  • Where the biggest unknowns are.
  • How much capacity is available.
  • What must happen before users can migrate.

The plan will change as the team learns more about the legacy system. Having one still gives the team a way to understand whether the deadline remains realistic.

What should be clear before modernization starts?

Before committing to a migration plan, answer four questions:

Why are we modernizing?

Identify the business constraints created by the existing system.

How will the old and new systems coexist?

Compare the temporary cost and risk of each migration approach.

How will expected behavior be defined and validated?

Document acceptance criteria and representative use cases, then test them with real users.

What needs to be true before the old system can be retired?

Define this separately from the launch of the replacement.

Any question the team cannot answer identifies work that should happen before rollout.

Modernization should remove constraints, not reproduce them

A legacy application is an important source of information, but it should not dictate every decision about its replacement.

Understand which business rules still matter. Make expected behavior explicit. Choose a migration strategy based on the real dependencies between the old and new systems. Then validate the replacement with the people who will depend on it.

The goal is not simply to replace old technology.

It is to leave the business with software that is easier to change, support, and rely on.

If you're planning a legacy modernization and need help understanding the existing system, comparing migration strategies, or defining a path to the replacement, let’s start a conversation.

‍

llms.txt