·
Nov 4, 2026
SmartSense Live 2026 | Food Safety Summit
SmartSense LIVE26 recap: SmartSense ONE’s launch, the Disruptive Technologies acquisition, AI assistant KAI, and what it means for food safety and compliance teams.

4
min read
Read more
Kaizen Teams


·
7
min

·
August 14, 2026

·
November 13, 2026


Pablo Manzoni
AI
AI
AI
UX Design
UX Design
UX Design
·
November 13, 2026
·
November 13, 2026
·
7
min read
Pablo Manzoni
A synthetic user is a constrained AI decision agent defined by twelve fields, from functional role and context to assumptions and abandonment rules.
In the previous post I built an early, working implementation, and the next question was whether the same rules could hold up in a repeatable, automated test.
This post is that next step: how I turned the framework into a Claude Code plugin, and the technical decisions behind adapting methods designed for people into something an AI can execute without cheating.
Give a model a URL and ask it to “find the usability issues.” It works halfway. And the “halfway” is the interesting part, It gives you a generic list, correct in the abstract, useless in practice.
A usability issue matters because of who encounters it and under what conditions.
Using an app from bed is not the same as using it on a factory floor. Urgency changes, lighting changes, attention changes, previous knowledge changes. The same confusing button can be irrelevant to a power user and an abandonment point for an operator wearing gloves.
The whole design comes from that observation: the AI does not evaluate the interface. It acts as a specific person in front of the interface.
The person brings the context with them. And the context turns a list of defects into a list of priorities.
An orchestrator controls the browser through Playwright MCP. It reads each screen as an accessibility snapshot: text, roles, states, no guessing pixels. Then it acts on specific elements.
The decision on each screen is made by an isolated subagent, which returns a JSON for each step:
{
"action": "...",
"clarityLevel": "High|Medium|Low",
"doubtDetected": true,
"reason": "...",
"abandoned": false,
"estimatedTimeSeconds": 40,
"emotionalState": "...",
"memory": "..."
}
Two rules make this look more like a person and less like an oracle.
The evaluator receives one screen at a time, without knowing how many are left or what comes next in the flow.
If the interface leaves room for a mistake, the synthetic user makes the mistake. It clicks where a person would click, not where it is convenient to click in order to complete the test. This is where the framework’s forbidden assumptions live. The agent cannot assume backend logic or mentally complete what the screen does not show.
The memory field travels from one step to the next. The emotional state is inherited and accumulates. A frustration +1 persists. This detects something that is structurally invisible to any test that evaluates screens separately.
Screen five does not necessarily fail because of screen five. It fails because the user gets there with accumulated frustration.
Evaluated alone, that screen passes. Evaluated by someone carrying three doubts and one broken promise, it triggers abandonment. In the first post, I wrote that doubt is not failure. It is the signal that reveals structural friction.
Emotional memory is that idea turned into architecture.
Each subagent gets a clean context. It knows the minimum required to do its job.
That ignorance is deliberate.
The agent acting as the user does not know what the orchestrator knows. It cannot compensate for bad design with knowledge a real person would not have.
Subagent
What it does
| Subagent | What it does |
|---|---|
| synthetic-screen-evaluator | Acts as the user on one screen and returns the JSON for that step |
| synthetic-flow-synthesizer | Reads the complete run and writes the report. It never simulates again |
| synthetic-profile-generator | Generates a complete profile from an approved spec, choosing from a controlled vocabulary |
| synthetic-autopilot-synthesizer | Consolidates N runs and classifies findings by convergence across users |
| heuristic-persona-generator | Creates the 3 persona raters based on the business being evaluated |
| heuristic-expert-evaluator | Detects violations of the 10 heuristics using forced enumeration |
| heuristic-persona-rater | Scores each finding from the experience of ONE persona. It runs ×3 |
| heuristic-report-synthesizer | Builds the final report using the already computed numbers |
A textbook heuristic evaluation uses three to five human evaluators because each human finds different problems.
My first experiment was literal, and it went meh.
I iterated until I reached two synthetic detection runs with different agents, coverage was extremely high, but it exposed another problem: an unmanageable list. Dozens of valid issues, very few important ones.
The final design separates those two jobs.
Based on Nielsen’s literature, an expert goes through each screen and is forced to produce a verdict for every heuristic:
Each verdict includes textual evidence from the snapshot, forced enumeration breaks the habit of reporting only the things that stand out.
Three synthetic personas are generated according to the business being evaluated:
They score the findings without seeing the expert’s conclusions. The same issue can matter very differently depending on what each persona brings to it.
The formula is business impact × usability impact, with agreement between personas as the tiebreaker.
This keeps issue detection and user impact as separate jobs: the expert identifies the violations, and the personas help determine which ones deserve attention first.
The plugin currently has three modes.
simulation-run (custom)
You build a profile field by field in the Synthetic User Builder, the tool I built to materialize the framework.
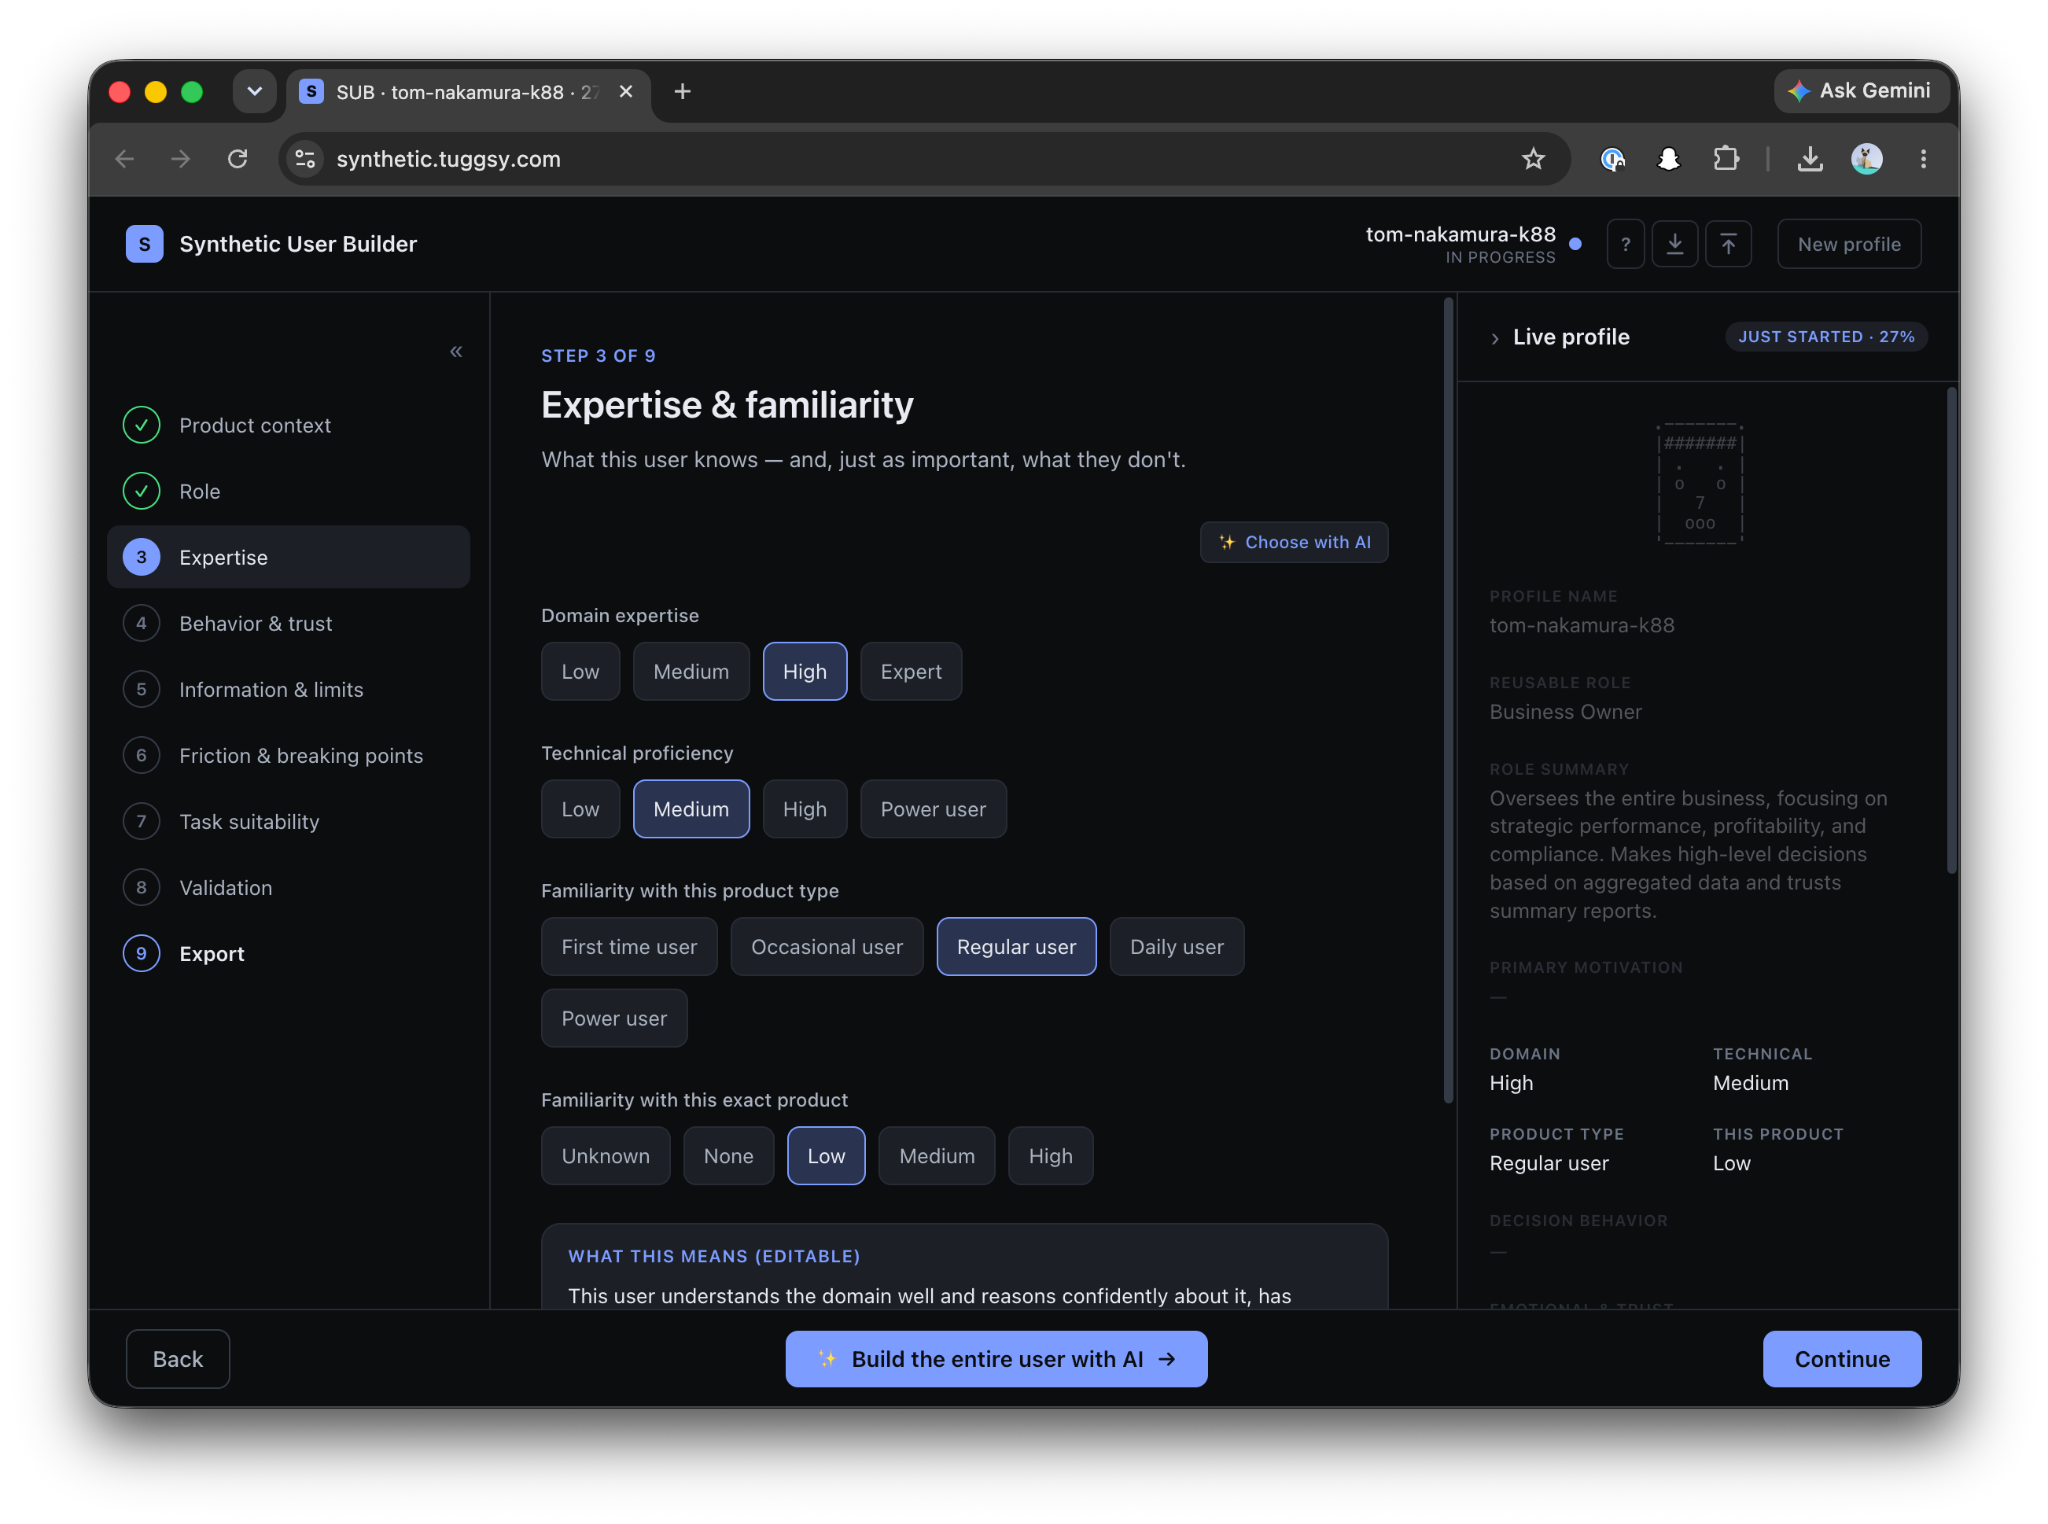
First come the attributes:
Only after that, and separately, comes the task.
The profile describes how someone decides, never what they have to do. That is why the same profile can be reused across tests.
simulation-auto (inferred)
You only give it the URL.
It researches the business, infers the typical roles, proposes users with tasks, and you adjust that proposal in natural language before anything runs.
heuristic-test (inspection)
The heuristic test described above, for one screen, one flow, or the entire site.
Every run leaves Markdown artifacts inside the project:
user-simulation-tests/
├── simulation/
│ ├── profiles/ ← users: the .md used for simulation + a .builder.json
│ │ that can be imported back into the Builder and edited manually
│ └── results/ ← one report per run + the consolidated report from auto mode
└── heuristic/
├── personas/ ← the 3 raters + business research, reused across runs
└── results/ ← reports with the prioritized findings table
Simulation reports include the full step by step flow, the emotional arc, risks, and a single “Fix this first.”
The consolidated report classifies findings by convergence: did one user suffer from this, or did all of them?
The decision to keep everything as accumulating .md files is strategic.
These are different runs, using different lenses, that can be analyzed together later, crossing heuristic violations with simulated emotions answers something no individual test gives us:
Of everything that is wrong, what actually matters?
What worked for me for the synthesis subagents:
A complete run consumes between 100k and 400k tokens, depending on the model and mode, in around 20 minutes.
That is the cost of a test that previously required coordinating the schedules of three professionals, and that can now run against every iteration of the product.
Here's a complete run against our site, kzsoftworks.com: a skeptical "Business Leader" profile, five live browser steps, and a full Markdown audit in under three minutes that names the exact moment the executive persona lost trust.
Every rule in the framework became an architectural constraint: clean context, one screen at a time, emotional memory, forbidden assumptions.
The plugin is open source: github.com/PabloManzoni/user-simulation.
Three commands, and the inferred mode only needs your URL.
If you try it and your synthetic user abandons on screen three, you already know what it means:
It is not failure. It is the signal.

Events
·
Nov 4, 2026
SmartSense LIVE26 recap: SmartSense ONE’s launch, the Disruptive Technologies acquisition, AI assistant KAI, and what it means for food safety and compliance teams.
4
min read
AI
UX Design
·
Oct 23, 2026
How a design system lets Marketing and Product teams use AI to build on-brand prototypes, based on Kaizen’s own experience and turnaround numbers.
6
min read